


B.Tech + M.S. by Research in CSE @ IIIT Hyderabad AI systems · agent reliability · evals · telemetry you can verify


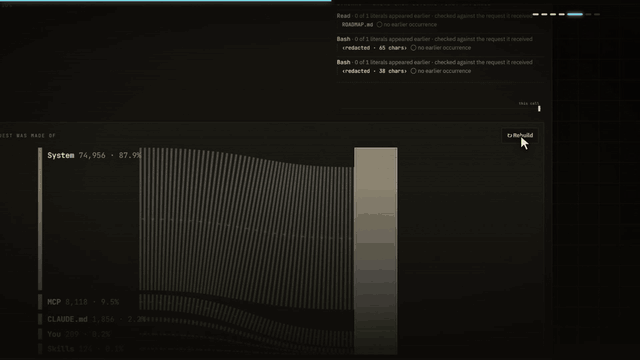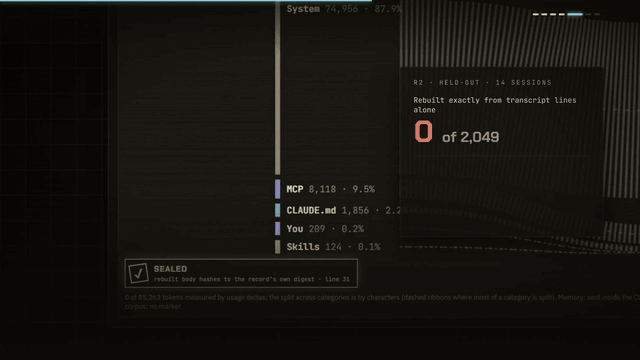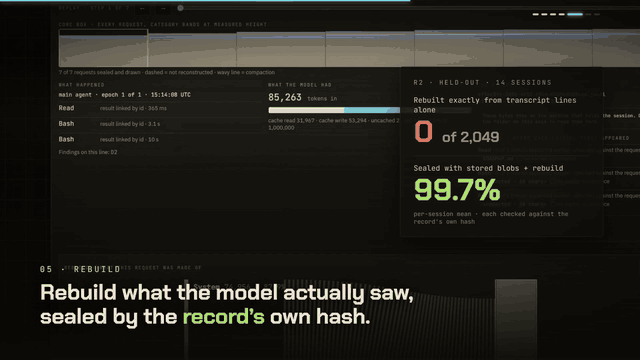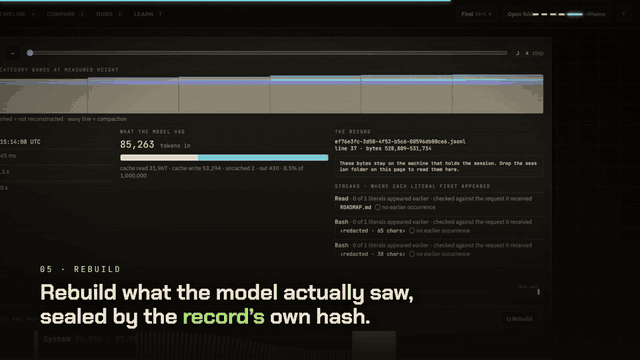
Can you trust your coding agent's telemetry? I summed the usage on every line of one of my own Claude Code sessions and got 20,195 output tokens. Counted once per message: 5,320. assay audits the record before you read anything into it: it states what was captured, runs 14 self-consistency checks with findings pinned to file, line and bytes, and rebuilds each API request to hash-match the transcript's own digest. Local-only, deterministic, no model in any verdict.
Live site · Explorer · Repo and limitations
| 🎓 Reliance Foundation Scholar | Merit-based national scholarship |
| 📄 Research paper, FMFP 2026 | ML for Darrieus hydrokinetic turbines (IIT Roorkee SPARK, under Prof. Chandra Shekhar Pant and Dan Singh Pimoli). The model's failure to generalize became the core result. |
| 🏢 Samsung R&D Bangalore | Research intern, Design Automation Lab |
| 🚀 Former President, E-Cell IIIT-NR | Ran E-Summit 2026: 1,700+ registrations, 375+ hackathon participants, ₹1.3L+ prize pool |
| 📈 Lateral entry to IIIT Hyderabad (LEEE 2026) | Simultaneous B.Tech + M.S. by Research in CSE, after a 9.44 CGPA at IIIT Naya Raipur |
| 🧠 Stanford Machine Learning Specialization | Completed on Coursera, Aug 2026 |
Agents and ML systems usually fail quietly: a confident wrong answer, a badly chosen tool, a trace that looks fine and isn't. I build the system, then break it on purpose to see what it does under pressure.
Canary is the clearest example. I planted facts in an agent's context, compacted it four different ways, and checked which facts survived. A channel rule died in 27 of 27 runs under the head+tail policy, and nothing in the agent's output hinted that it was gone.
surfacelab asks the same question of tool choice. On tools with one clear job each, models were near perfect; on real MCP servers loaded together, gpt-oss found the only right tool 77% of the time, and its misses landed on tools whose descriptions read alike.
assay turns the same question on the logs themselves. When I tried to rebuild exactly what a model was sent from its own transcript, it worked for 0 of 2,049 requests; with the stored blobs, 99.7% hash-matched. Anything it can't prove stays "unresolved" instead of being guessed. I also tested whether an LLM could do the checking: AUROC 0.48 on 379 human-labelled spans, so no model gets near a verdict.
That's the through-line in my research direction: calibrated uncertainty, interpretable policies, and evals and telemetry that catch silent failure.
| Project | What it does | Stack | Links |
|---|---|---|---|
| assay | Audits Claude Code telemetry: states what was captured (Capture Level L1–L4), runs 14 self-consistency checks with findings pinned to file, line and byte range, and rebuilds each API request to hash-match the transcript's own digest (99.7% of held-out requests; 0 of 2,049 from lines alone). A naive sum of the log overcounted output tokens 3.8× in one run. An LLM judge scored AUROC 0.48, so no model touches a verdict. One user's sessions, run locally. | TypeScript, zod, Vitest, OpenTelemetry | Live site · Repo |
| surfacelab | Open evaluation of how AI agents choose MCP tools: 12 preregistered experiments, 3 models, 396 recorded calls on 82 tools from 11 real servers, drawn as a scroll-driven 3D observatory. Found that misses land on look-alike descriptions, and that adding a second browser server changed the agent's first move in 14 of 24 requests. | Python, Three.js/WebGL, Docker | Observatory · Repo |
| Canary | Open-source kit that plants facts in an agent's context, compacts it four ways, and measures which facts survive. 3 canaries, 4 policies, 27 seeds per cell, preregistered, every run replayable. | Python | Live demo · Repo |
| ChunkScope | Visualizes a RAG pipeline end to end, so you can see how chunking and retrieval choices change what the model receives | Next.js, FastAPI, Three.js/WebGL, pgvector | Being upgraded for deployment |
| Nexora | Five-agent research pipeline (planner, executor, critic, contradiction engine, synthesizer) on LangGraph. Deep research in under 3 minutes. | LangGraph, Qdrant, Redis Pub/Sub, Groq | Being upgraded for deployment |
| C Shell | A Unix shell written from scratch in C for my OS course: parsing, process creation, job handling | C | Course project |
| Area | What I use |
|---|---|
| Languages | Python, C, JavaScript, TypeScript |
| Agents and LLM systems | LangGraph, MCP, Groq, multi-agent orchestration, context compaction, evals |
| Telemetry and testing | OpenTelemetry, Vitest, Playwright, JSON Schema (zod) |
| Retrieval and data | pgvector, Qdrant, PostgreSQL, Redis (Pub/Sub) |
| Web and visualization | Next.js, React, FastAPI, Three.js/WebGL |
| Systems | Linux, xv6 (MLFQ scheduler), a Unix shell in C |
| Shipping | Git, Docker, Vercel, GitHub Actions |
🧪 Building now (click to expand)
Canary, surfacelab and assay are a set of agent-harness projects, built one at a time. What's next on assay:
- A hooks (L2) importer: no run has been captured at L2 yet
- An intake for redacted runs from other people, since every number so far is one user's
- Extending the parent-chain check to links of non-event lines, a blind spot found by planting a known fault
Each gets linked here once it has a working demo, not before.
🎓 Background (click to expand)
- Research: ML for hydrokinetic turbines, IIT Roorkee (SPARK), published at FMFP 2026
- Industry: Samsung R&D Bangalore (Design Automation Lab); business analyst at RootVestors
- Education: IIIT Hyderabad (2026 to 2029, B.Tech + M.S. by Research); previously IIIT Naya Raipur
- Certifications: Stanford Machine Learning Specialization (Coursera); DSA (takeUforward)
- Leadership: E-Cell IIIT-NR (President; earlier People Ops), MUN IIIT-NR, Technovate
- School: ISC 2023: 96.75 · ICSE 2021: 98.80
This section refreshes itself every 6 hours via GitHub Actions.
|
|
Last refreshed: 13 Nov 2026, 04:58 UTC
| asmit.shaw@research.iiit.ac.in | |
| asmit-shaw | |
| 🐙 GitHub | 1Ash0 |
| 🎓 Affiliation | IIIT Hyderabad, B.Tech + M.S. by Research in CSE |
Working on agent reliability, evals, telemetry, or RAG failure modes? Let's compare notes: LinkedIn.