
A collection of Spark related information, solutions, debugging tips and tricks, etc. PR are always welcome! Share what you know about Apache Spark.
Spark executor memory(Reference Link)
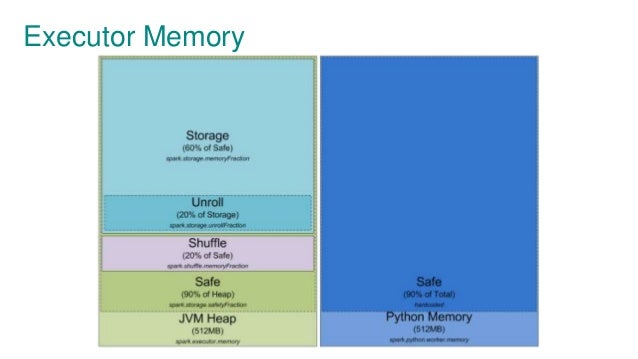
spark-submit --verbose(Reference Link)
- Always add
--verbose optionsonspark-submitto print the following information:- All default properties.
- Command line options.
- Settings from spark conf file.
Spark Executor on YARN(Reference Link)
Following is the memory relation config on YARN:
- YARN container size -
yarn.nodemanager.resource.memory-mb. - Memory Overhead -
spark.yarn.executor.memoryOverhead.

- An example on how to set up Yarn and launch spark jobs to use a specific numbers of executors (Reference Link)
- Tune the numbers of
spark.sql.shuffle.partitions.
Avoid using jets3t 1.9(Reference Link)
- It's a jar default on Hadoop 2.0.
- Inexplicably terrible performance.
- reduceByKey

- groupByKey

GC policy(Reference Link)
- G1GC is a new feature that you can use.
- Used by -XX:+UseG1GC.
Join a large Table with a small table(Reference Link)
- By default it's using
ShuffledHashJoin, the problem here is that all the data of big ones will be shuffled. - Use
BroadcasthashJoin:- It will broadcast the small one to all workers.
- Set
spark.sql.autoBroadcastJoinThreshold.
- If your task involves a large setup time, use
forEachPartitioninstead. - For example: DB connection, Remote Call, etc.
- The default Java Serialization is too slow.
- Use Kyro:
- conf.set("spark.serializer", "org.apache.spark.serializer.KryoSerializer");
- The
/tmpis probably full, checkspark.local.dirinspark-conf.default. - How to fix it?
- Mount more disk space:
spark.local.dir /data/disk1/tmp,/data/disk2/tmp,/data/disk3/tmp,/data/disk4/tmp
- Mount more disk space:
java.lang.OutOfMemoryError: GC overhead limit exceeded(ref)
- Too much GC time, you can check that on Spark metrics.
- How to fix it?
- Increase executor heap size by
--executor-memory. - Increase
spark.storage.memoryFraction. - Change GC policy(ex: use G1GC).
- Increase executor heap size by
shutting down ActorSystem [sparkDriver] java.lang.OutOfMemoryError: Java heap space(ref)
- OOM on Spark driver.
- This usually happens when you fetch a huge data to driver(client).
- Spark SQL and Streaming is a typical workload which needs large heap on driver
- How to fix?
- Increase
--driver-memory.
- Increase
java.lang.NoClassDefFoundError(ref)
- Compiled okay, but got error on run-time.
- How to fix it?
- Use
--jarsto upload and place on theclasspathof your application. - Use
--packagesto include comma-sparated list of Maven coordinates of JARs.
EX:--packages com.google.code.gson:gson:2.6.2
This example will add a jar of gson to both executor and driverclasspath.
- Use
- Error message:
Exception in thread "main" org.apache.spark.SparkException: Job aborted due to stage failure: Task 0.0 in stage 0.0 (TID 0) had a not serializable result: com.spark.demo.MyClass Serialization stack:- Object is not serializable (class: com.spark.demo.MyClass, value: com.spark.demo.MyClass@6951e281)
- Element of array (index: 0)
- Array (class [Ljava.lang.Object;, size 6)
- How to fix it?
- Make
com.spark.demo.MyClassto implementjava.io.Serializable.
- Make
- How to fix it?
- Upload Spark-assembly.jar to Hadoop.
- Set
spark.yarn.jar, there are two ways to configure it:- Add
--conf spark.yarn.jarwhen launching spark-submit. - Set
spark.yarn.jaronSparkConfin your spark driver.
- Add
java.io.IOException: Resource spark-assembly.jar changed on src filesystem (Reference Link)
- Spark-assembly.jar exists in HDFS, but still get assembly jar changed error.
- How to fix it?
- Upload Spark-assembly.jar to Hadoop.
- Set
spark.yarn.jar, there are two ways to configure it:- Add
--conf spark.yarn.jarwhen launching spark-submit. - Set
spark.yarn.jaronSparkConfin your spark driver.
- Add
- In Java, you can use org.apache.spark.util.SizeEstimator.
- In Pyspark, one way to do it is to persist the dataframe to disk, then go to the SparkUI Storage tab and see the size.