





1.5x faster and 4.4x less memory than smalot/pdfparser. Actively maintained, MIT licensed, and built from scratch for PHP8.1+
🦉 This library is written by a human who understands all of its code. As such, it is small enough for a person to have a mental image of it, and no cognitive offloading is needed. AI-generated PRs are not rejected outright, but they should be small and focused.
Previously, there wasn't a PDF library that allows parsing of PDFs that was open source, MIT licensed and under active development. The PDFParser by smalot, while having been very useful over the years isn't under active development anymore. The parser of Setasign is not MIT licensed and not open source. And several other packages rely on java/js/python dependencies being installed that are called by PHP behind the scenes, losing any type information and underlying structure.
Instead, this package allows for parsing of a wide variety of PDF files while not relying on external dependencies, all while being MIT licensed!
| Metric | prinsfrank/pdfparser | smalot/pdfparser |
|---|---|---|
| Speed | On average 1.5x faster, up to 110x faster on complex PDFs | baseline |
| Memory | On average 4.4x less memory | baseline |
| Success rate | 100% of test files | 95.3% |
| Encrypted PDFs | Supported | Not supported |
| Extract as markdown | Yes, including: Headings, Bold, Italic, Links! | No |
| Multi-column support | Yes | No |
| PHP version | PHP 8.1+ | PHP 7.1+ |
| Active development | Yes | Limited maintenance |
| PHPStan Level | 10 (max) | 3 |
View detailed benchmark results
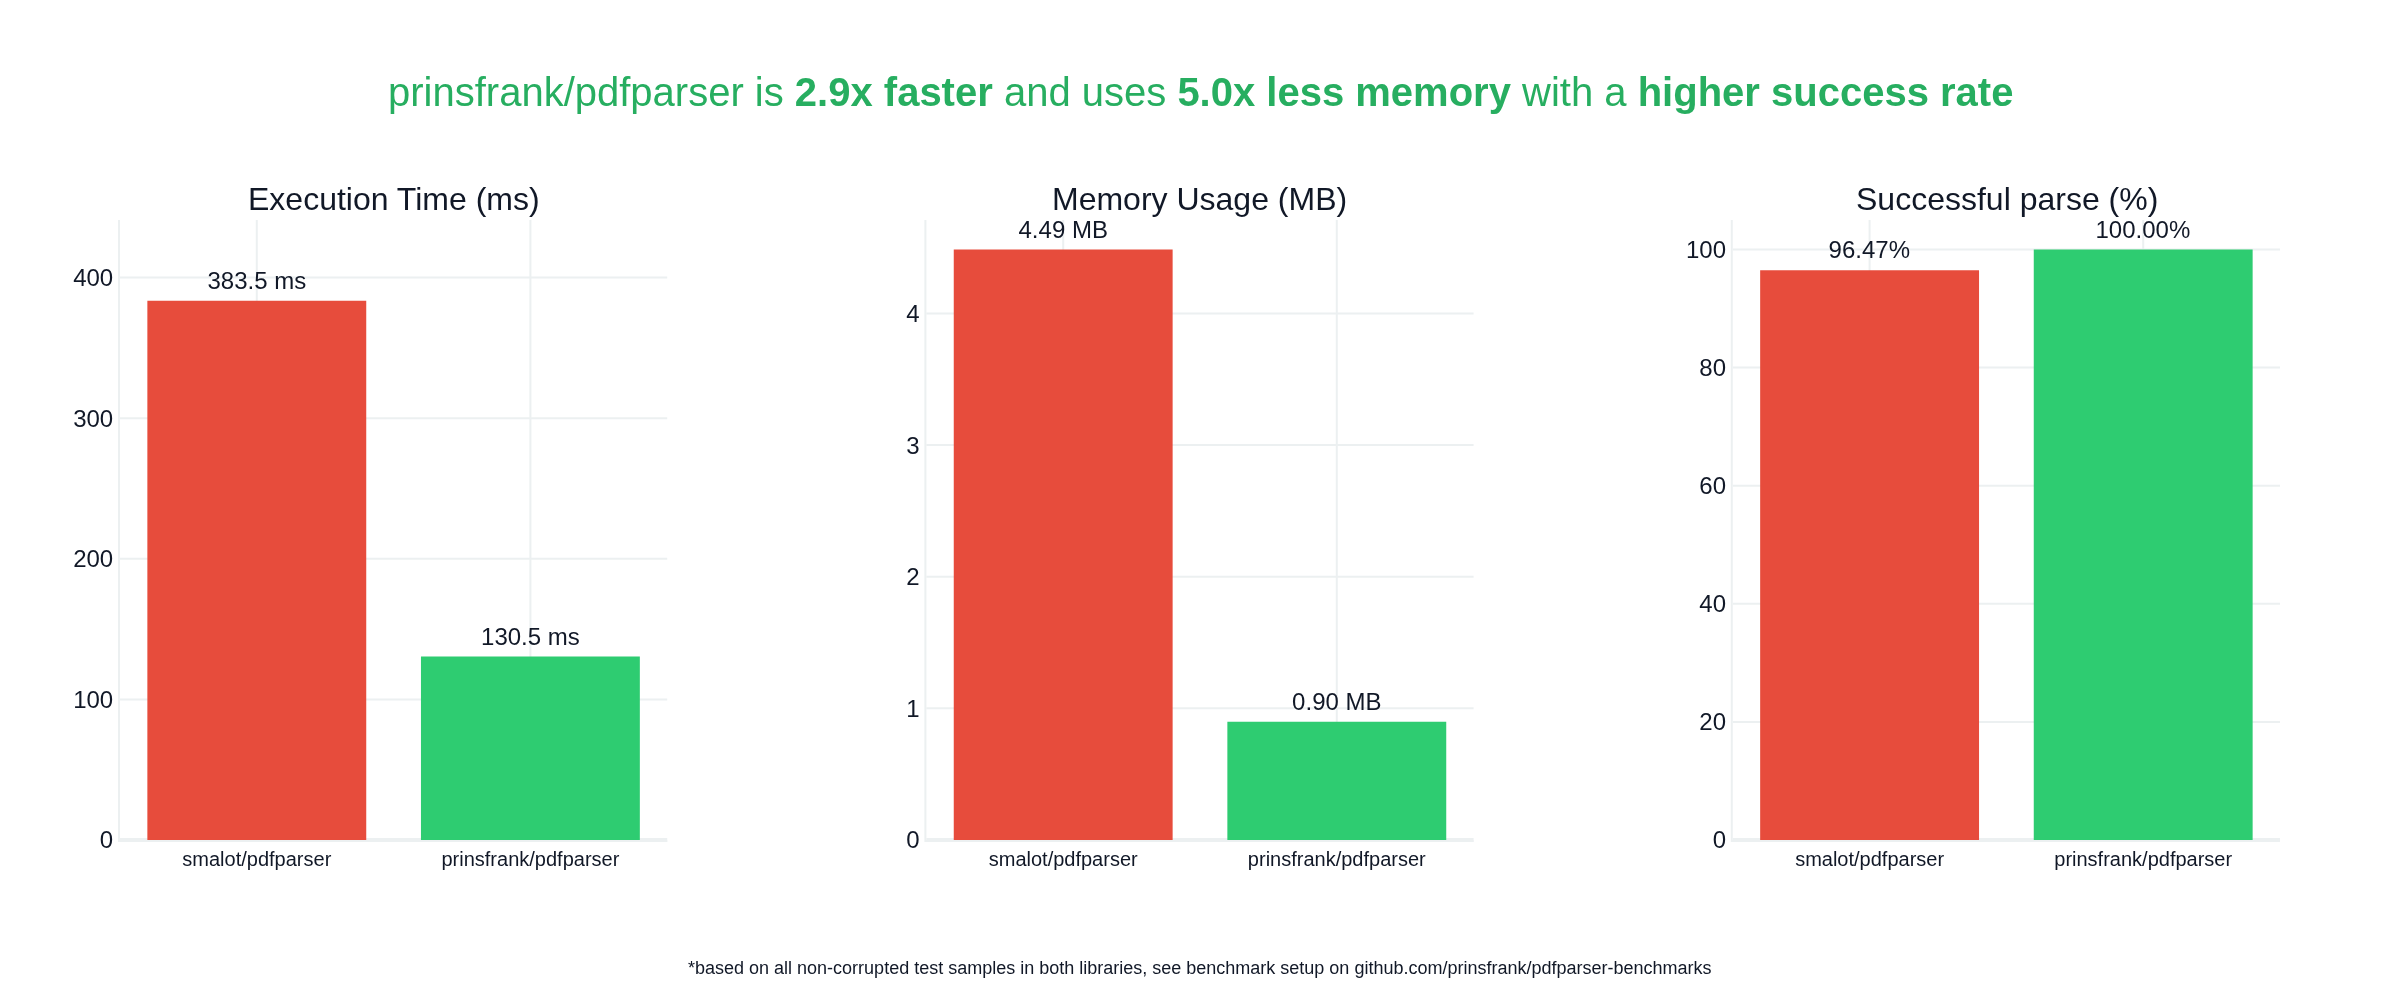
Or see the benchmark repository for more details.
To start right away, run the following command in your composer project;
composer require prinsfrank/pdfparserInstallation without Composer
If you don't want to install this package using Composer, or cannot due to some constraints, you can still download a phar file of the latest release, which bundles all the required dependencies. To do so, head to the "releases" section on the github repository, and click on "pdfparser.phar" under "Assets". Place the phar file somewhere you can access it from your code
As you don't have Composer to handle autoloading for you, you'll need to register the autoloader from the phar file. To do so, simply add the following line at the top of your custom bootstrap script or the file you want to parse PDFs in:
require 'phar://pdfparser.phar/vendor/autoload.php';
The most common use case - extracting text from a document - is then just as simple as this;
use PrinsFrank\PdfParser\PdfParser;

$document = (new PdfParser())
    ->parseFile($path);

$document->getText();
Or, if you prefer markdown:
use PrinsFrank\PdfParser\PdfParser;

$document = (new PdfParser())
    ->parseFile($path);

$document->getMarkdown();If you depend on this package and want to support its maintenance, please consider sponsoring me. I'll continue maintaining and releasing updates regardless, but sponsorships help cover the time it takes to review changes and keep everything accurate.
To open a PDF file, you'll first need to load it and retrieve a Document object. That can be done by either parsing a file directly, or parsing a PDF from a string variable.
Parsing a PDF from a file directly is the easiest option. To do so, simply call the parseFile method on a PdfParser instance:
use PrinsFrank\PdfParser;

$document = (new PdfParser())
    ->parseFile(dirname(__DIR__, 3) . '/path/to/file.pdf');
By default, this loads the file into memory while parsing. This greatly improves parsing speed, at the cost of a bigger memory footprint. If you want to reduce the base memory footprint and use a file handle instead, you can set the second parameter useInMemoryStream to false.
It is also possible to parse a PDF from a string in a variable. To do so, pass the string as an argument for the parseFile method on a PdfParser instance.
use PrinsFrank\PdfParser;

$pdfAsString = file_get_contents(dirname(__DIR__, 3) . '/path/to/file.pdf');

$document = (new PdfParser())
    ->parseString($pdfAsString);
If you want to decrease the average memory footprint, you can also do so here, by setting the useFileCache parameter to true. This will result in the file content being written to a temporary file and the parser using the handle to that file from then on. This will be at the cost of speed.
Once you have opened a file from the filesystem with parseFile or from a string variable using parseString, you'll get back an instance of a Document.
While initially parsing the document, a small number of variables are populated in the Document instance that allow for further accessing of that document. This includes:
- The public
$streamproperty: a PHP stream handle to the file in memory or on the filesystem. - The public
$versionproperty: Information about the PDF version of the file. - The public
$crossReferenceSourceproperty: A parsed crossReference table or stream, containing several crossReference(Sub)Sections that contain information about objects stored in the document and where to find them. - The public
$securitywith the user and owner password if supplied - The private
$pagesproperty to cache any pages that have already been retrieved. This property is only set when the pages are actually retrieved using thegetPagesmethod. (See below)
The document also contains several methods to retrieve specific objects from it. Those are discussed below.
If you want to quickly retrieve all text from a document, you can use the getText method.
A PDF is organized in objects. Not all objects are created equally. Some objects might be a Page, while others a Font. Some objects might be Generic and without a specific type. There are currently 18 specific types, and a generic object type. Some of those will be specified below.
Code specific for certain object types lives in that object types' decorator. Retrieving text for a Page makes sense, retrieving the text from a Font not so much, so the Page decorator contains the getText method. Below you'll find some documentation for specific object decorators.
If you want to retrieve an object by its number, you can call the $document->getObject($objectNumber) method:
$page = $document->getObject(42);The most important data type in a PDF is a dictionary. It contains key-value pairs with information about objects. In principle, any dictionary can contain any key-value pair. To retrieve the dictionary for an (un)compressed object, you can simply call the getDictionary method:
/** @var \PrinsFrank\PdfParser\Document\Object\CompressedObject\CompressedObject $object */
$object->getDictionary();
In practice, most dictionaries are of a certain subtype. As such, this library contains several Decorators that wrap the dictionaries, providing easy access to dictionaries of specific types:
- Annotations
- Catalog
- EmbeddedFile
- EncryptDictionary
- Field
- FileSpecification
- Font
- InformationDictionary
- InteractiveForm
- Page
- Pages
- XObject
If you expect a dictionary to be of a certain type, you can retrieve the decorated object by supplying the expected decorator as an argument for the getDictionary method:
/** @var \PrinsFrank\PdfParser\Document\Object\CompressedObject\CompressedObject $object */
$object->getDictionary(\PrinsFrank\PdfParser\Document\Dictionary\Decorator\InformationDictionary::class);