Repository navigation
Conversation


The PR description supplies sufficient testing evidence: a build followed by five built-CLI E2E tests at the reviewed head. No testing-record finding. No PR code was executed. |

 SaulMoro
left a comment
SaulMoro
left a comment
There was a problem hiding this comment.
This was generated by AI during triage.
@hobostay @jeff-r2026 Thanks for this. Measuring whether a team change helps is the right question. It is the same question #1379 answers, though, and I'd rather not merge #1559 alongside it. Two suite formats and two harnesses for one job would split the results and double the upkeep.
Both alternate arm order, both require the check to fail at the starting commit before trials run, and both record tokens and cost. Where they differ:
| #1559 | #1379 |
|---|---|
JSON suite with two arms, before and after team refs |
suite.yaml arms over a matrix of tool, model and team (pulled, none, any ref, without a given asset) |
| Pass rate per arm, with no interval on the difference | Paired trials, a 95% Newcombe interval on the difference, and "not separated" when the interval crosses zero |
| Its own timeout stop in a standalone script (the CI review found it can leave the child running on Windows) | Runs as a workflow through teamai workflow start --benchmark, with the CLI's shared process-tree stop |
| Report file per run | Results kept in run records and shown on the dashboard's Benchmarks page |
The dashboard is where the difference shows. This is what a team sees after a run:
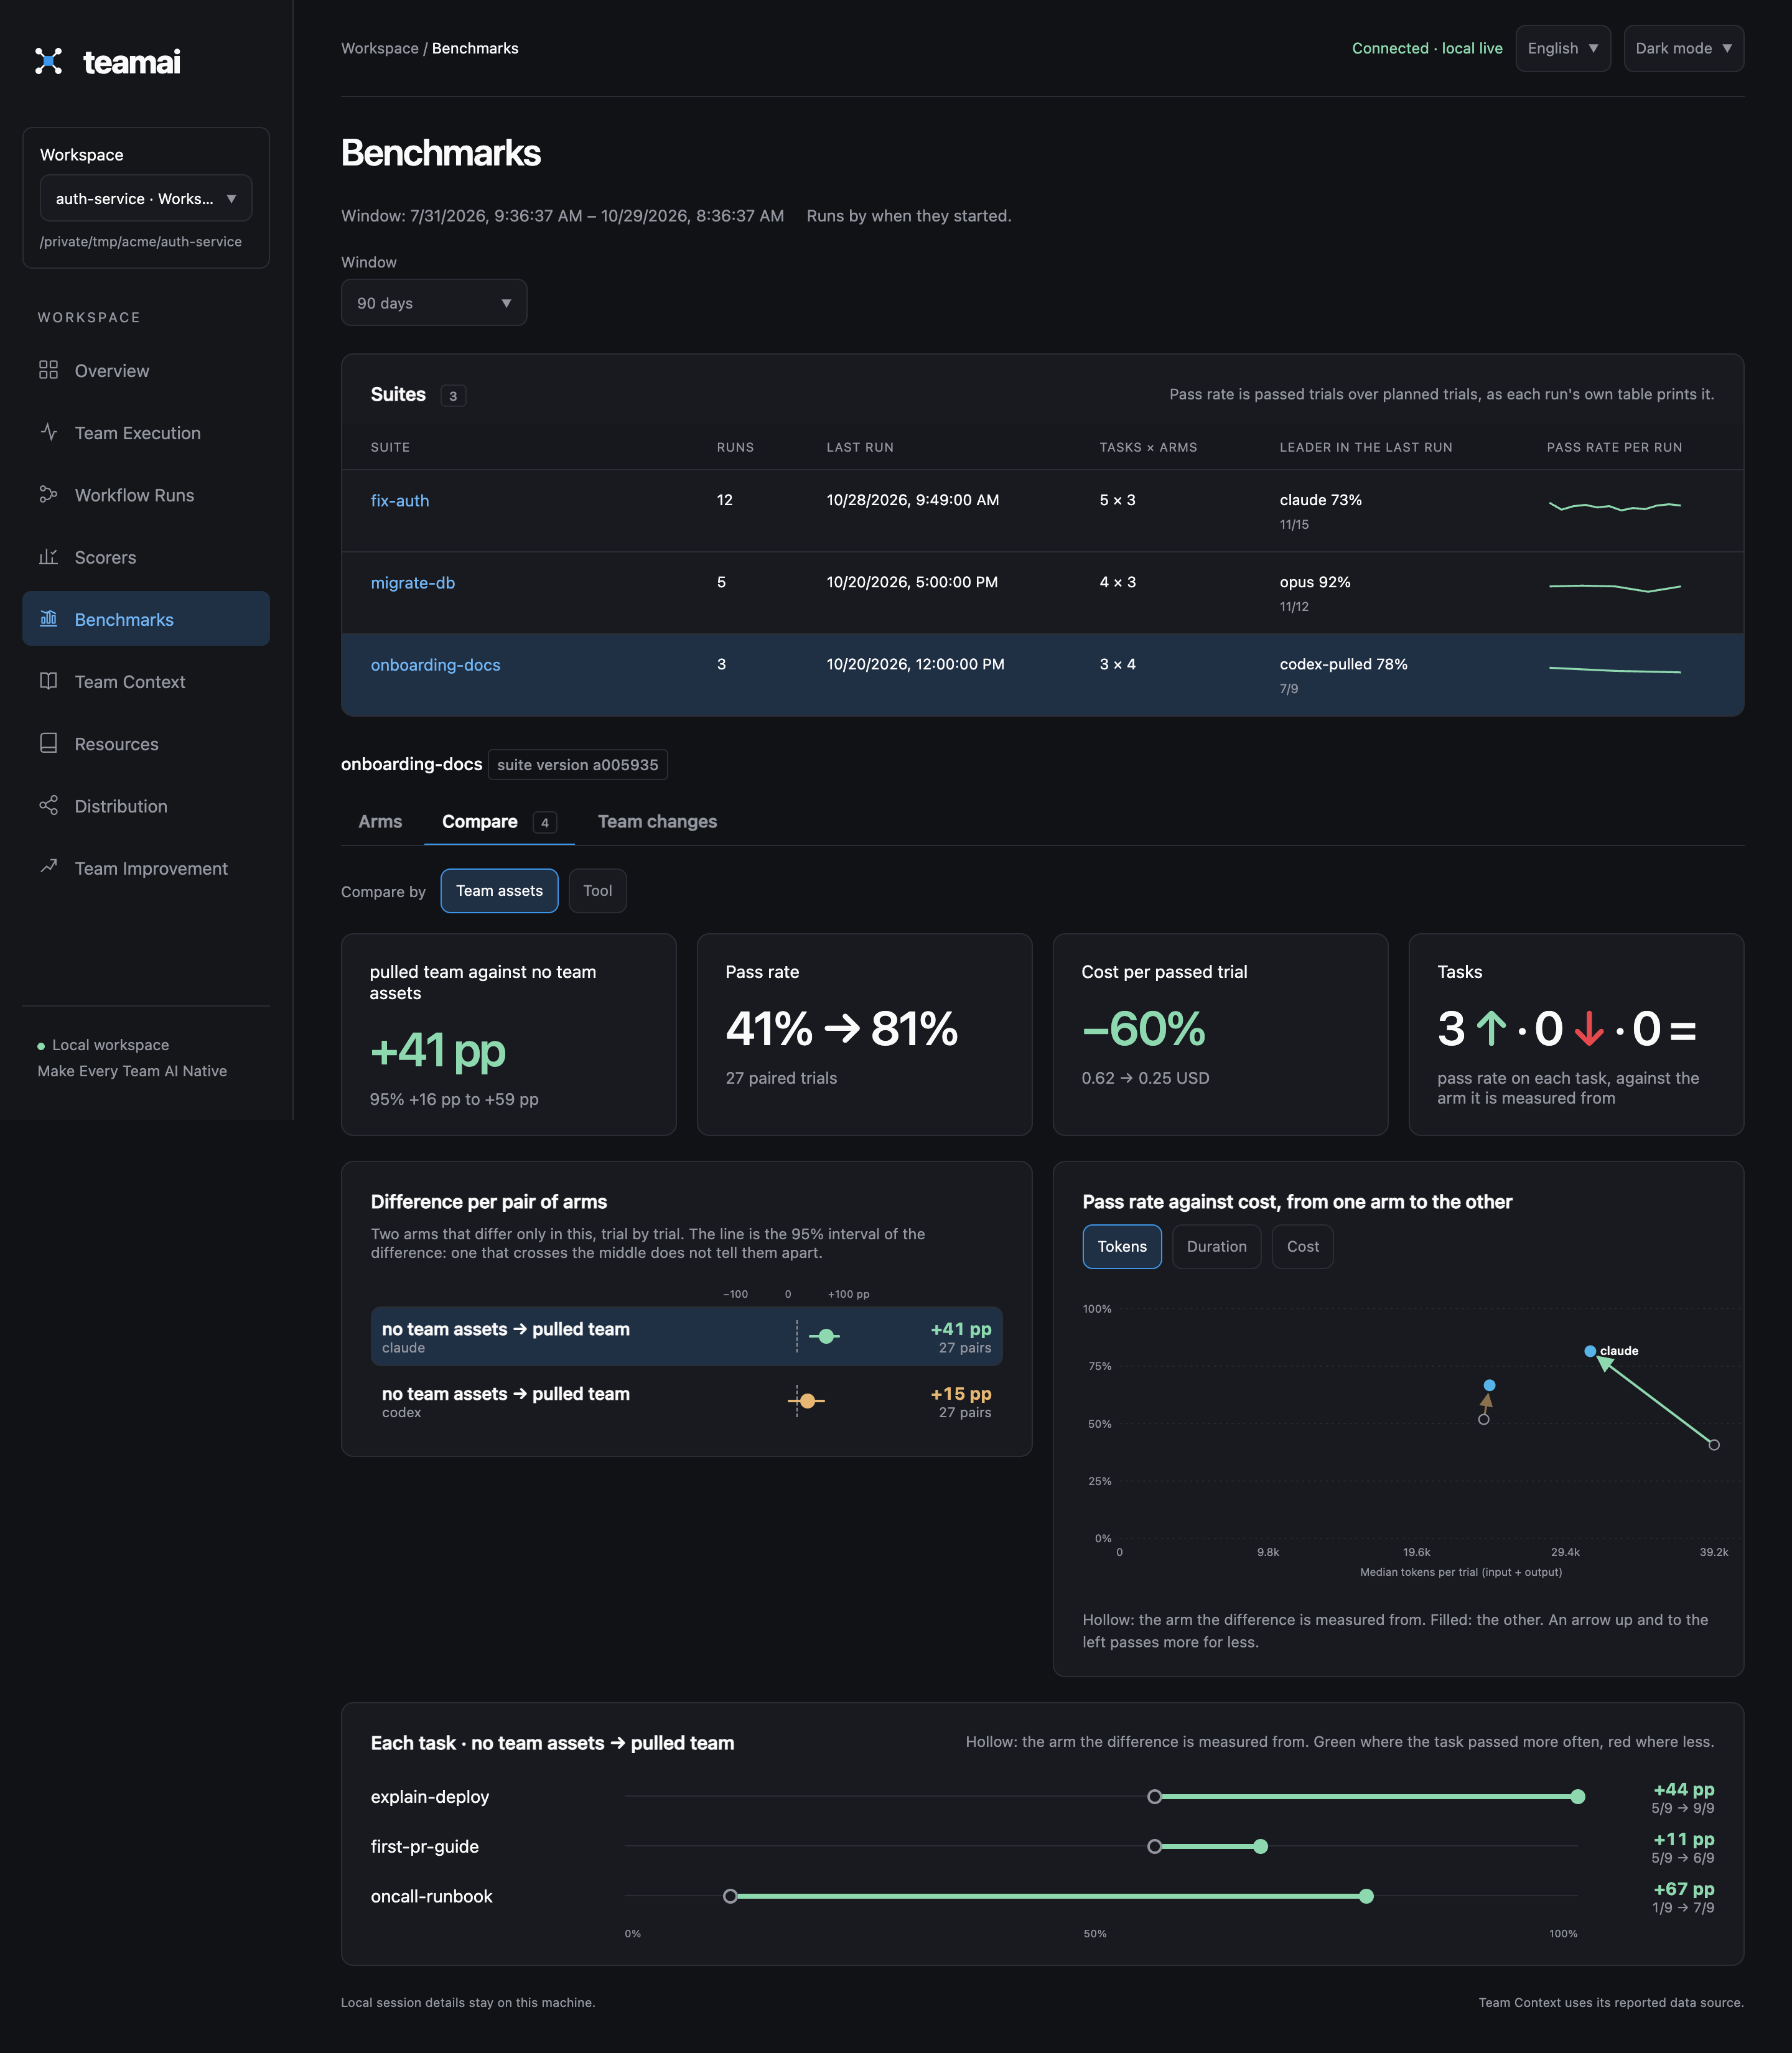
Compare: pulled team against no team assets, per tool, with the interval.
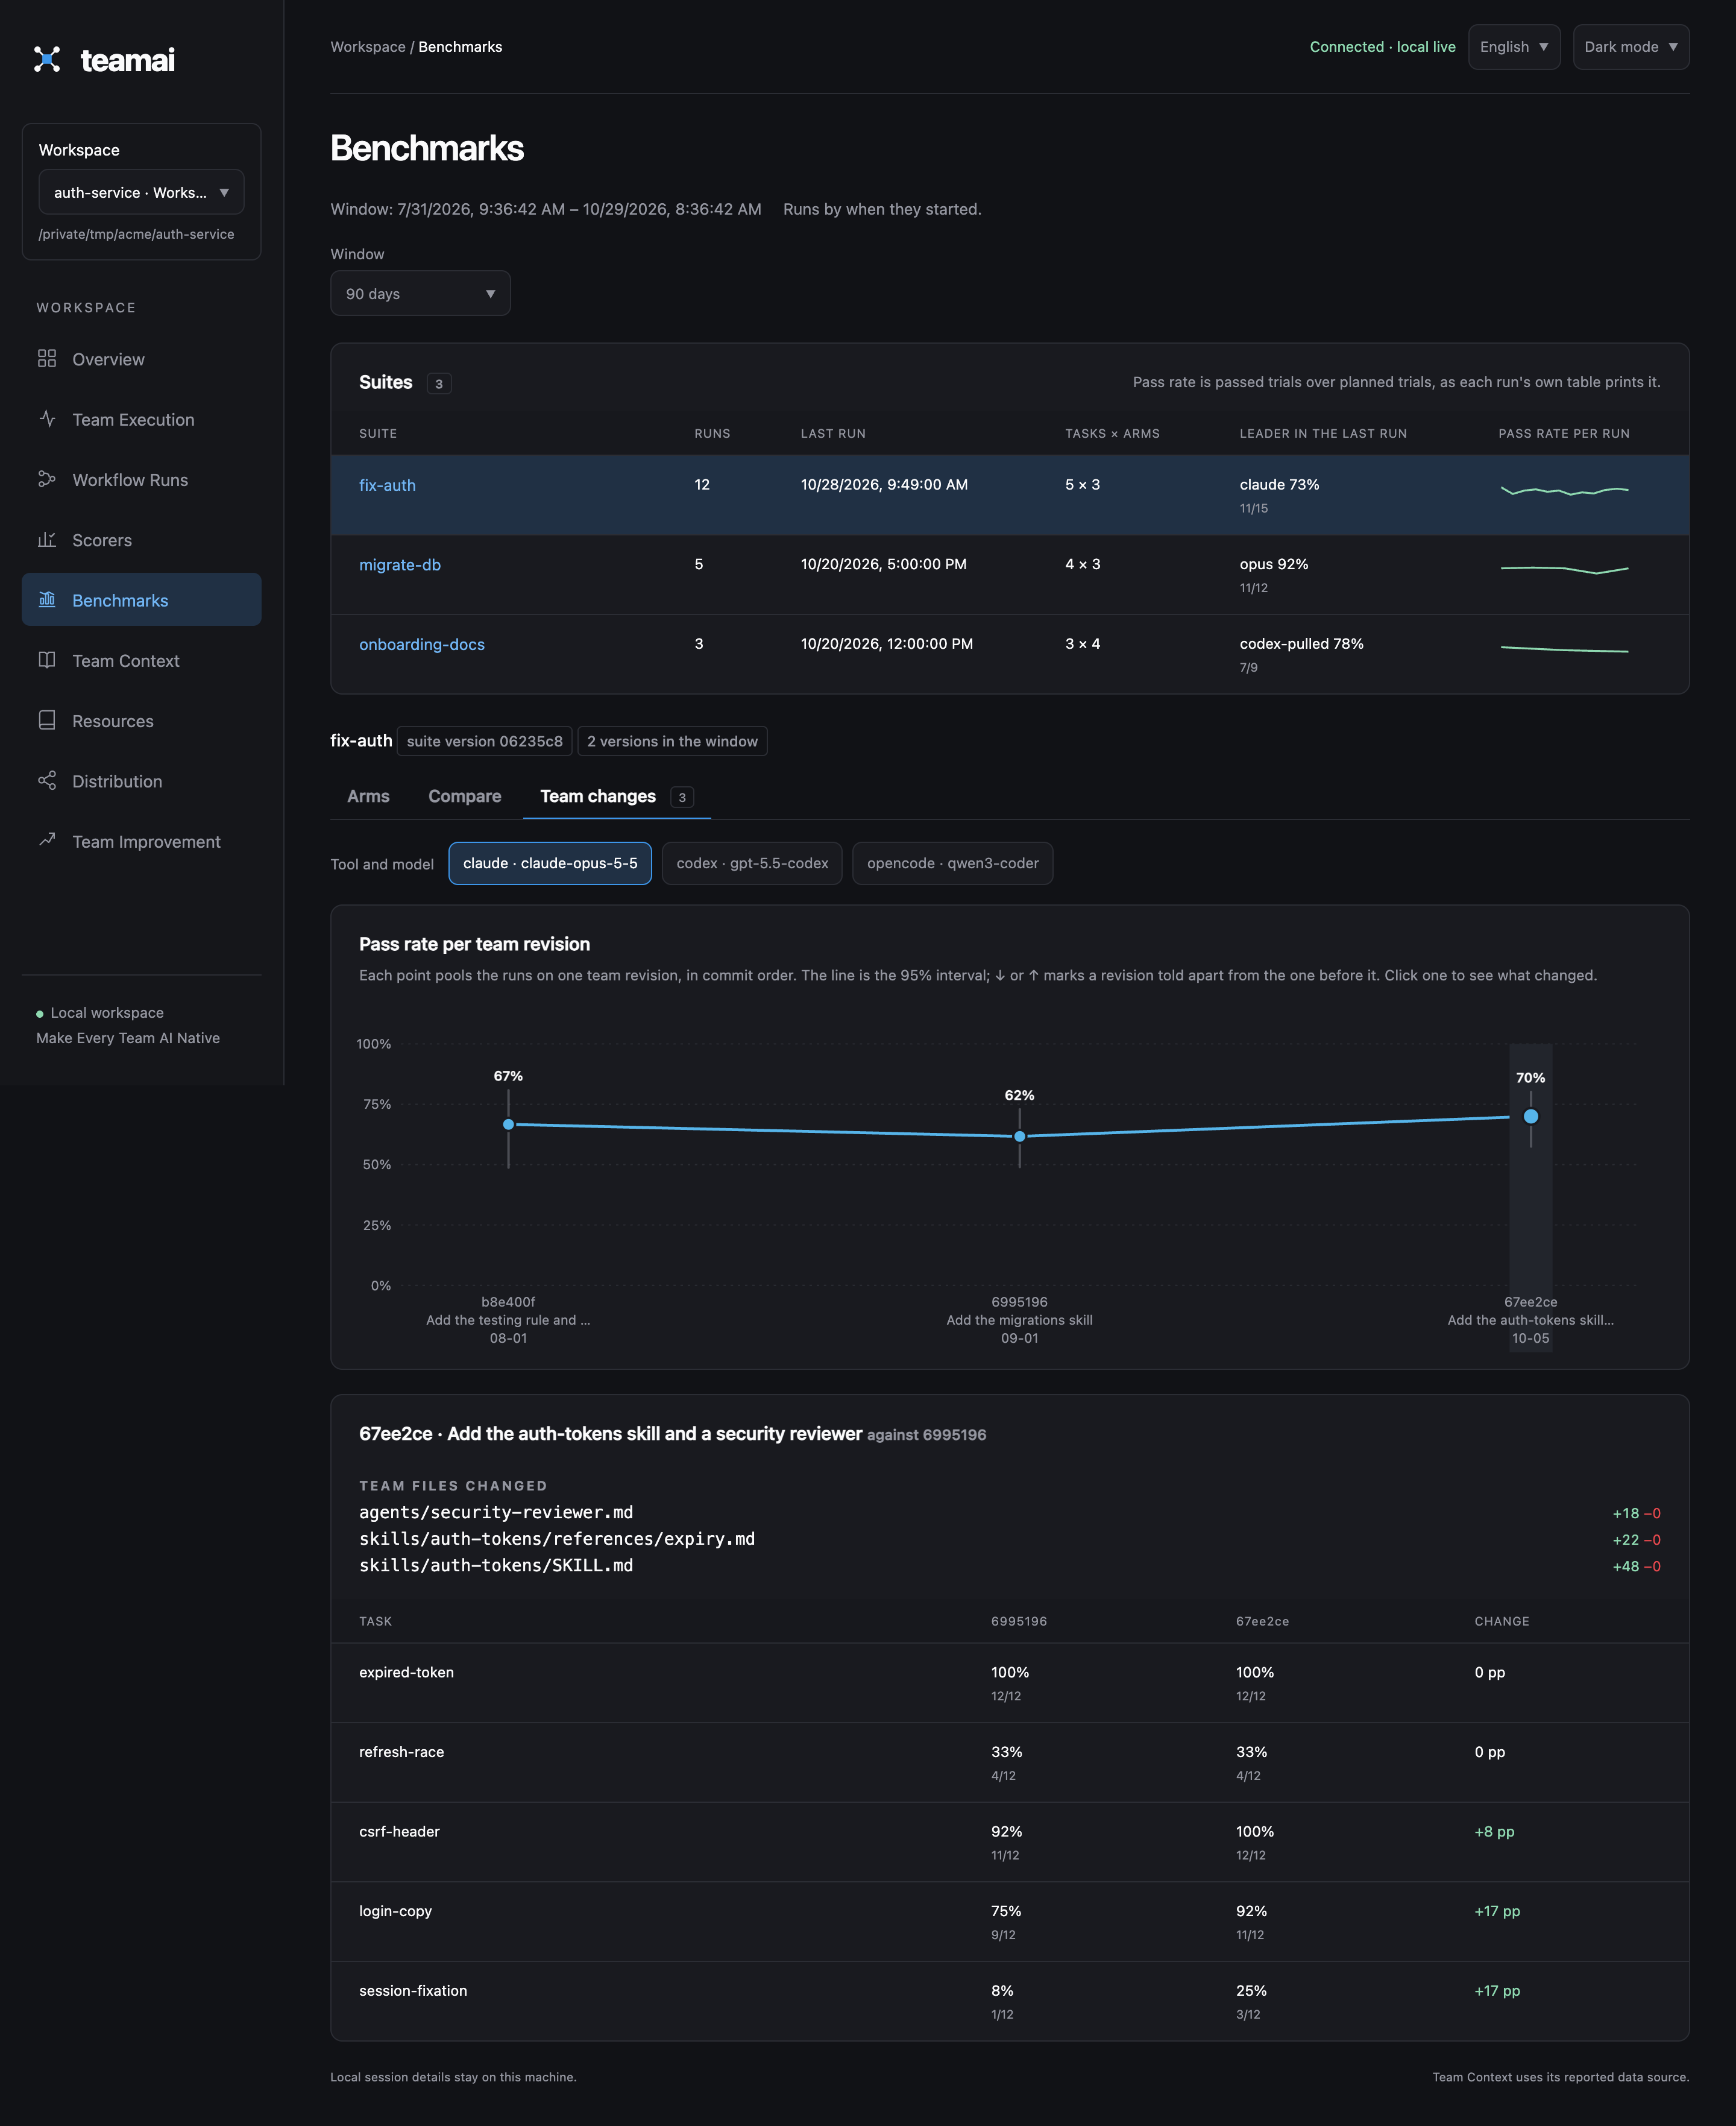
Team changes: one tool and model across team revisions, with the files each revision changed. This is the before/after comparison #1559 aims for, over any number of revisions.
Arms: every arm over time, and pass rate against cost.
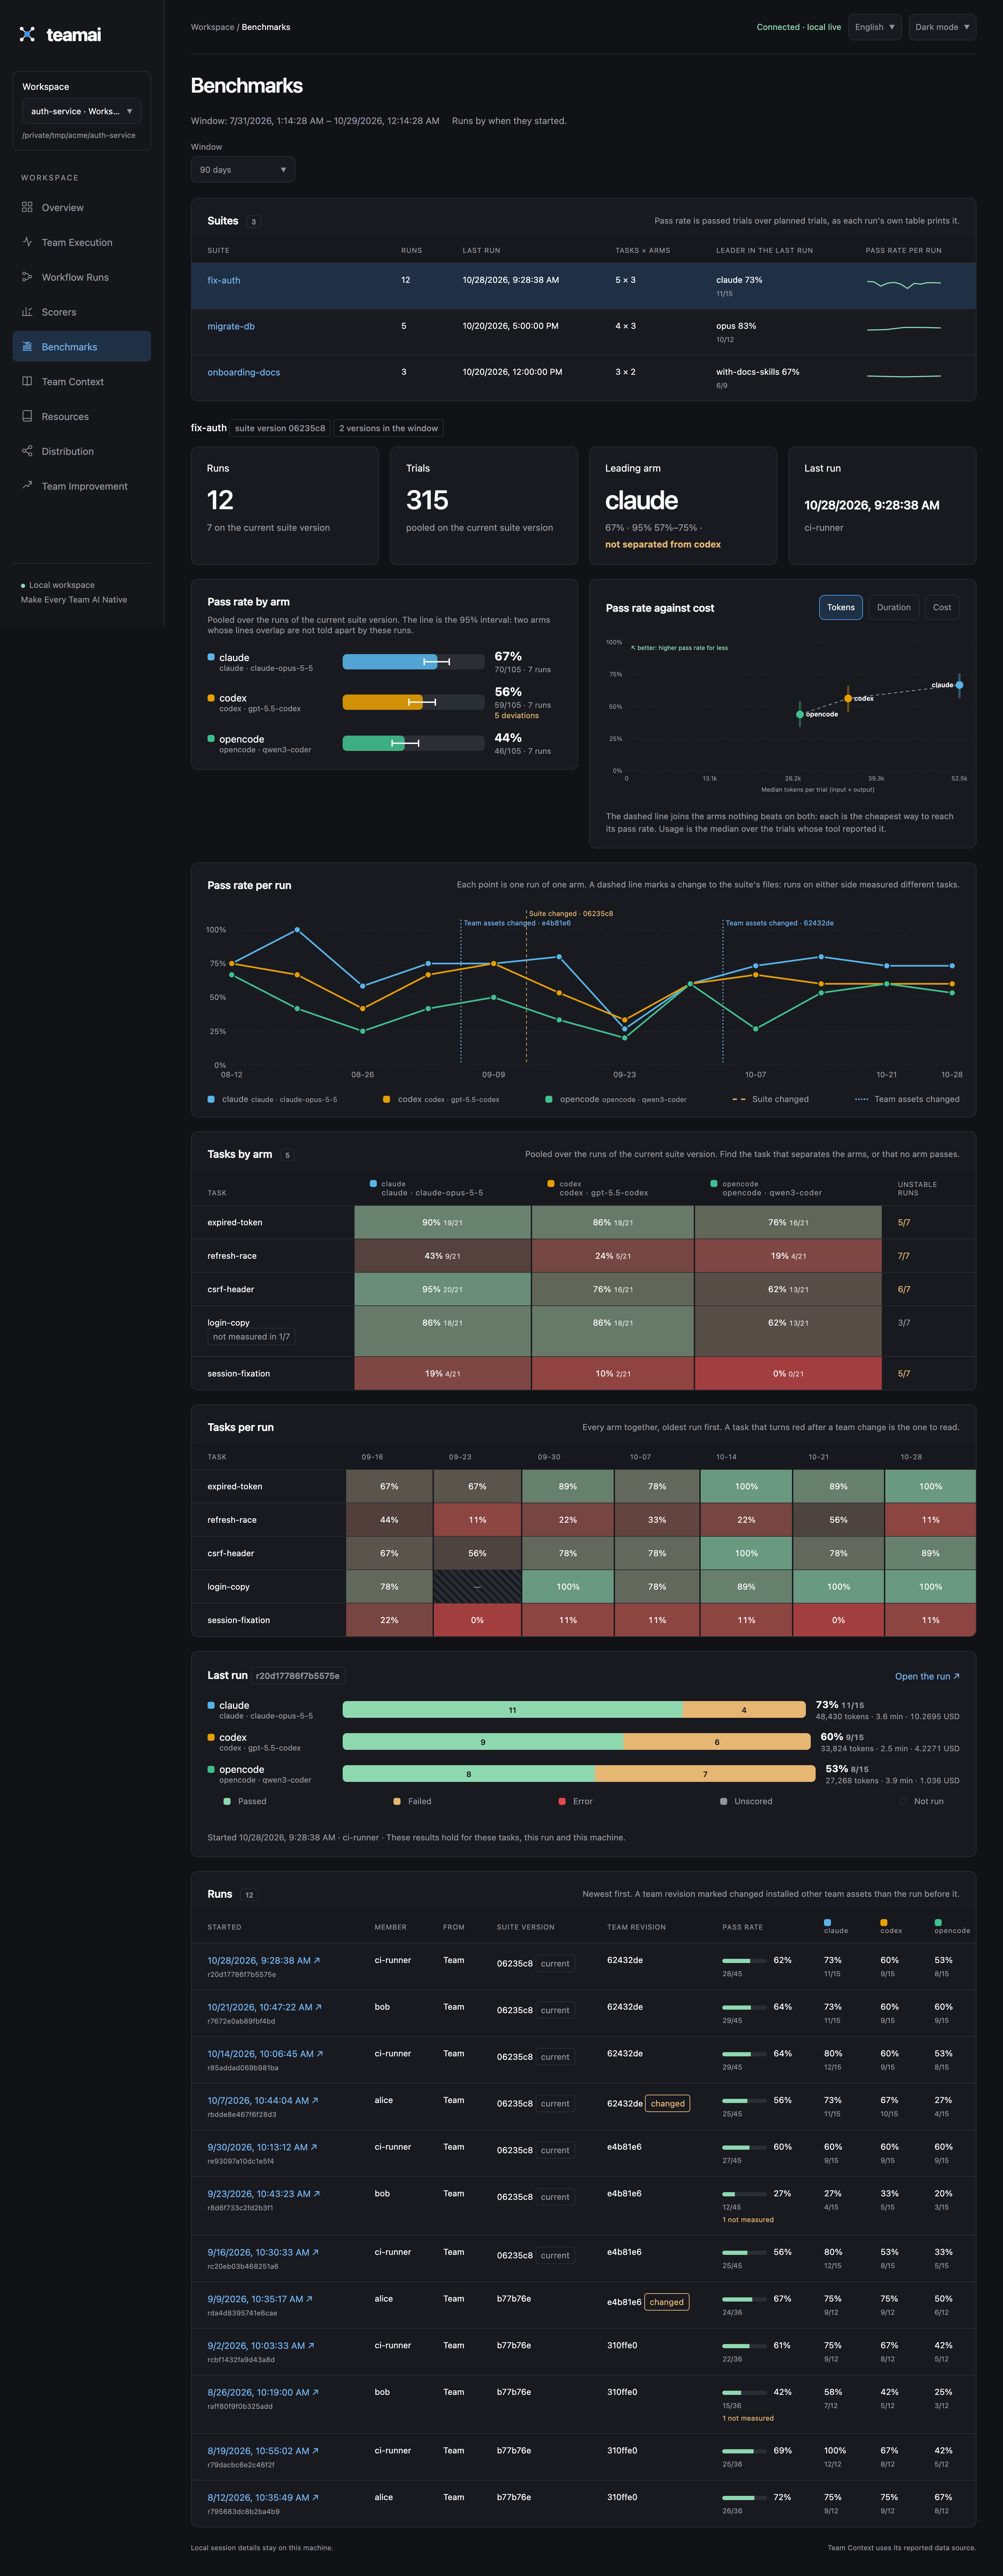
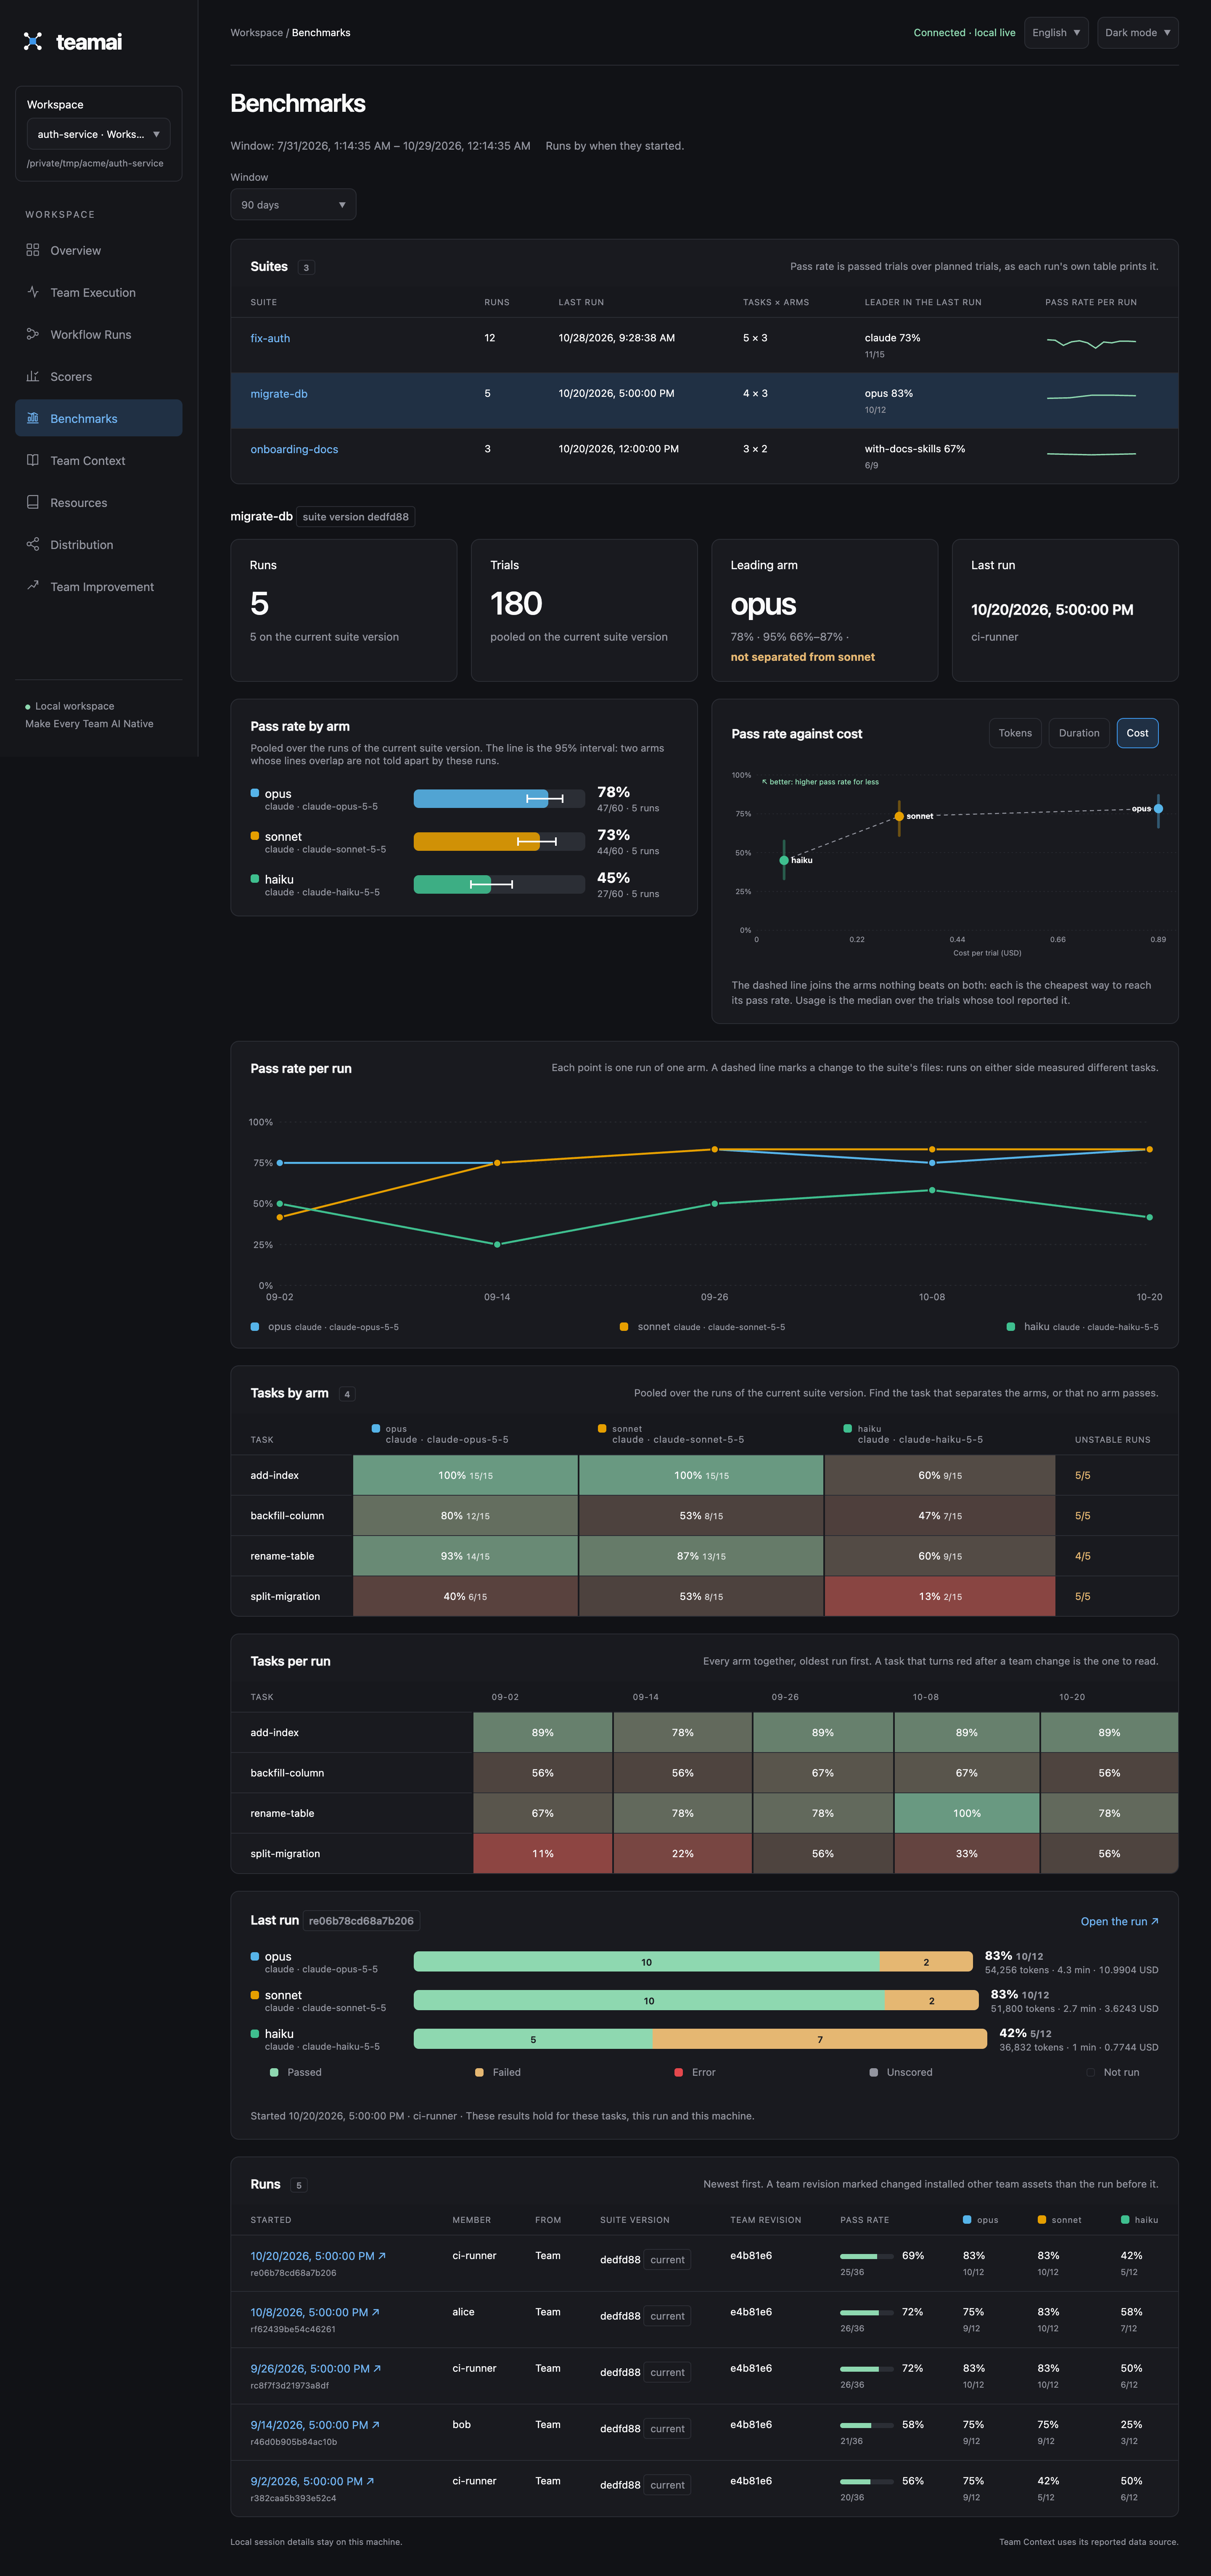
In the example runs it answered questions like these. Team assets help claude on onboarding docs by +41 pp (95% +16 pp to +59 pp) over 27 paired trials, at 60% less cost per passed trial. The +15 pp for codex is not separated from zero. On migrate-db, sonnet reaches 73% at 0.31 USD a trial against opus at 78% for 0.89 USD.
My suggestion is to close this one and bring the suites you had in mind to #1379 as suite.yaml files. If you see something here that #1379 handles worse, please point it out there and we'll fold it in.

|
Closing as a duplicate of #1379, which answers the same question (does a team change help on fixed tasks) with paired confidence intervals and is wired into workflows and the dashboard. As SaulMoro noted, two suite formats and two harnesses for one job would split the effort. Thanks @hobostay — ideas from here are welcome as follow-ups on #1379. |


Summary
Add a developer harness that compares before/after team asset revisions on the same code commit, tasks and runner. Each trial uses fresh code/team clones, HOME and tool configuration roots; the code clone has no origin and pull uses a disposable local mirror.
The harness freezes refs, requires each baseline check to fail before an agent runs, alternates arm order, checks results objectively, and emits JSON plus Markdown reports with paired gains/regressions, planned/not-run/error counts, duration and optional measured token/cost totals. Missing usage remains unknown. Timeouts stop the runner's process tree; interrupts preserve the partial report and stop further trials.
Type of Change
Test Plan
Windows, Node 24.22.1, Git 2.52.0, 2026-10-29. Head: a9c16f3.
The E2E suite calls the built TeamAI CLI and verifies fixed asset commits, actual rule delivery, alternating order, paired improvement, source repositories unchanged, a no-delivery arm, missing usage, rejection of passing baselines, runner error classification, and termination of a timed-out runner plus its child before a delayed external write.
The runner in these E2Es is deterministic, not a model. These results validate the harness, not the effectiveness of any particular AI assets. No paid model benchmark or real GitHub/GitLab provider was run; additional platforms and the full unit suite are left to CI. CI runs the report unit tests and the existing fork-safe E2E suite discovers the new integration file.
Related Issues
Related #1249 and #1137. Complements the proposed workflow benchmark implementation in #1379.
Notes for Reviewers
Run: node scripts/benchmark-assets.mjs /path/to/suite.json /path/to/report.json
docs/dev/asset-benchmarks.md defines the suite and runner contract. Runner commands use argv arrays and receive prompts on stdin; credentials can be supplied through the runner environment/wrapper because trial HOME is deliberately empty. Optional role/project selections are shared across arms.
This adds no public CLI command, workflow schema or dependency, and can merge independently of #1379. It is directory/process isolation, not a security sandbox for untrusted agents. The chosen setup, team assets and runner are commands the operator intends to execute.
Shared state: original repositories are read only for cloning; each trial owns its config, assets and usage file. The harness alone writes the aggregate reports, including checkpoints after every trial. The runner can report measured usage through TEAMAI_BENCHMARK_RESULT.