You signed in with another tab or window. Reload to refresh your session.You signed out in another tab or window. Reload to refresh your session.You switched accounts on another tab or window. Reload to refresh your session.Dismiss alert
{{ message }}
Repository navigation
[Bug]: New Codex runtime entries can disable existing shadow-home providers #5817
T3's Codex shadow-home setup only links entries that already exist in the shared home when materialization runs. If a later Codex update creates a new top-level runtime entry in both the shared and shadow homes, the next materialization rejects the shadow copy and disables the provider.
Codex 0.147 introduced queue_1.sqlite, which triggers this today. The same failure can recur when Codex adds another home entry.
Reproduction
Configure the documented multi-account layout: one shared homePath and another account using that homePath plus a separate shadowHomePath.
Start with no queue_1.sqlite in either home and let T3 materialize the shadow home.
Run Codex 0.147 against both effective homes. Codex creates a regular queue database in each.
Refresh provider status or restart T3.
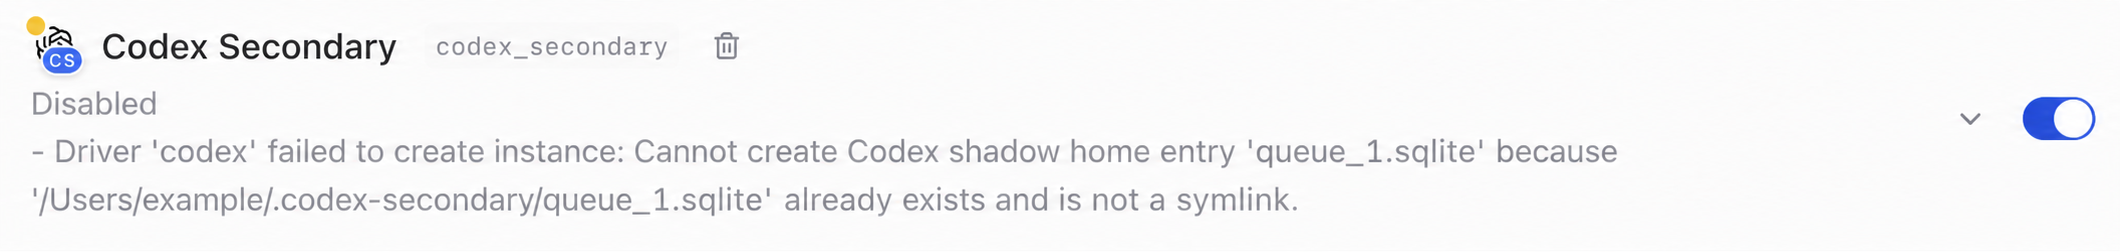
The shadow-home provider becomes disabled:
Driver 'codex' failed to create instance: Cannot create Codex shadow home entry 'queue_1.sqlite' because '<shadow-home>/queue_1.sqlite' already exists and is not a symlink.
A minimal unit repro is to create regular sharedHome/queue_1.sqlite and shadowHome/queue_1.sqlite files, then call materializeCodexShadowHome(layout).
Codex added the queue DB in openai/codex@b87981a. In the affected installation, the shared DB and two shadow DBs were automatically created within six seconds, confirming this was runtime-created state rather than a copied home.
Expected behavior
Codex upgrades that add runtime entries should not disable existing shadow-home providers. T3 should reconcile ownership safely or offer a targeted recovery path without silently deleting user data.
Acceptance criteria
New Codex home entries created after an earlier materialization do not leave providers disabled.
The solution is resilient to future filenames rather than only adding queue_1.sqlite to an allowlist.
Existing data is preserved; SQLite families such as the base DB, WAL, and SHM are handled together.
Tests cover creation between materialization passes and an existing regular shadow entry.
Environment
T3 main at 1a003e383ac6b10258b8100c2617d938c4f06c69
Codex CLI 0.147.0
macOS 26.5.2, Apple Silicon
Workaround
With related processes stopped, backing up and removing the shadow queue_1.sqlite, queue_1.sqlite-wal, and queue_1.sqlite-shm files allows T3 to create the shared link. This is manual, potentially data-destructive, and does not address future Codex entries.
Reacted by Ewen GUERIN, Andrei, FredericDierenBescherming, Aleksandr Stasko, Alan Iván Flores Juárez, Lorenz Bank and PressF10
changed the title [-][Bug]: Codex 0.147 queue DB disables shadow-home provider instances[/-][+][Bug]: New Codex runtime entries can disable existing shadow-home providers[/+]on Aug 9, 2026
This has recurred across several recent T3 Code Nightly and Codex updates.
On startup or provider refresh, the secondary Codex provider is disabled during materializeCodexShadowHome. T3 encounters a regular SQLite runtime sidecar in the shadow home where it expects a symbolic link, then aborts provider creation.
Exact error
Driver 'codex' failed to create instance:
Cannot create Codex shadow home entry 'logs_2.sqlite-shm'
because 'C:\Users\<user>\.codex_p\logs_2.sqlite-shm'
already exists and is not a symlink.
The corresponding server trace reports:
CodexShadowHomeEntryConflictError:
Cannot create Codex shadow home entry 'logs_2.sqlite-shm'
because 'C:\Users\<user>\.codex_p\logs_2.sqlite-shm'
already exists and is not a symlink.
at CodexHomeLayout.ensureSymlink
at materializeCodexShadowHome
Previous occurrences on the same machine failed on other members of the same class of runtime files:
In this occurrence, the divergence was specifically:
base .sqlite file: symbolic link
-wal sidecar: regular shadow-local file
-shm sidecar: regular shadow-local file
This is slightly different from the original #5817 reproduction, where the shadow base database itself is described as becoming a regular file.
Recurrence evidence
Retained local logs show repeated failures on at least two consecutive days:
August 19: repeated provider-creation failures on memories_1.sqlite-shm
August 20: repeated provider-creation failures on logs_2.sqlite-shm
An earlier retained error also references queue_1.sqlite
The problem has returned after multiple manual recoveries and subsequent updates or restarts. It is not an isolated stale file left by a single interrupted process.
Different SQLite families become affected at different times. Some sidecars already existed from the previous day, while others were created or rewritten during the next T3/Codex run.
Impact
The complete secondary Codex provider is marked disabled.
Provider creation fails before the account can be used.
The provider remains unavailable across refreshes and restarts.
The first conflicting filename changes between occurrences.
Removing only the filename shown in the UI is insufficient because additional regular sidecars may remain.
The default provider and shared Codex home continue to work.
The secondary account authentication file remains valid.
The failure occurs during shadow-home materialization, before normal provider use.
Recovery confirmation
For diagnostic purposes, I backed up and moved all eight regular *.sqlite-wal and *.sqlite-shm files out of the shadow home. I did not modify the private auth.json or models_cache.json files.
I then disabled and re-enabled only the affected provider instance.
Its stated goal—keeping newly created Codex SQLite state shadow-local and treating a base database plus its WAL/SHM sidecars as one family—matches the recurring behavior observed here.
However, my captured state includes a sidecar-only divergence: the shadow base .sqlite entry remained a symbolic link while its -wal and -shm entries were regular files.
The PR description and diff appear to select shadow-local ownership when the shadow base database is already a regular file. I cannot confirm whether it also covers the observed case where only the WAL/SHM members have become regular files.
This Windows reproduction may therefore be useful for validating #7201 against both forms:
A regular shadow base database plus its sidecars.
A symlinked shadow base database with regular shadow WAL/SHM sidecars.
I am not proposing a separate implementation here. I am documenting the additional observed state so that the existing fix can be evaluated against the complete failure mode.
Adding updated Windows findings here as requested when #17005 was closed as a duplicate.
Environment
Windows, T3 Code desktop
T3 Code: 0.0.46-nightly.20261007.2787
Codex CLI: 0.161.0
Multiple Codex provider instances sharing a Codex home, with separate shadow homes for authentication
Observed failure
Three Codex providers failed to initialize with this sanitized error:
Driver 'codex' failed to create instance:
Cannot create Codex shadow home entry 'memories_1.sqlite-shm'
because '<shadow-home>/memories_1.sqlite-shm'
already exists and is not a symlink.
Inspection confirmed the sidecar-only state already described in this issue: base SQLite databases were symlinks to the shared home, while some -shm and -wal files were regular files in the shadow homes. Some WAL files were nonempty.
In the installed build, materializeCodexShadowHome attempts to link shared-home entries, and ensureSymlink rejects these existing regular files. The initial creation of the conflicting files was not captured; no fresh-install reproduction or repository regression test was run.
Workaround and verification
The conflicting files were backed up and moved out of the shadow homes, allowing T3 to recreate the links. Each affected provider's launch arguments were also configured to set sqlite_home explicitly to the shared Codex directory.
After T3 reloaded the settings, all three provider connection probes succeeded. No regular SQLite sidecar conflicts remained at that check. Long-term recurrence has not yet been tested.
This confirms the failure on the versions above and records the observed recovery. It is not a recommendation to delete SQLite sidecars or a claim that a permanent upstream fix has been verified. Related shared-directory approach: #9229.
Another entry for this issue, from Codex 0.161.0: cloud-config-bundle-cache.json. This one should not be linked, either.
Environment
T3 Code: 0.0.46-nightly.20261007.2774 (desktop)
Codex CLI: 0.161.0
macOS 27.0.1, Apple Silicon
Two Codex accounts: the default ~/.codex, and a second instance with shadowHomePath set to ~/.codex-t3/work
What happened
After a T3 restart, the second instance showed only "Disabled" in Settings → Providers, with its toggle still on. Its status cache had stopped updating at the restart. The settings were unchanged.
cloud-config-bundle-cache.json existed as a regular file in both the shared home and the shadow home. In the installed build, PRIVATE_ENTRY_NAMES is auth.json and models_cache.json, so materializeCodexShadowHome tries to link this file and ensureSymlink rejects the regular copy. I did not find the error text in the server trace. I am going by the file state and the code.
Why linking is the wrong fix for this file
The file is per-account. It holds chatgpt_user_id, account_id, and the workspace's signed enterprise config_toml and requirements_toml, with a one-hour expiry. If it were shared, one account could pick up another account's workspace policy. It belongs with auth.json and models_cache.json.
Linking also does not last. I deleted the shadow copy and turned the provider off and on. The provider came back, but within seconds there was a regular file in the shadow home again, and the shared copy had not changed. So the next restart would disable the provider again.
Workaround
A small job deletes the shadow copy every two minutes, so a restart does not find one. Codex fetches the bundle again when it needs it. This only matters until the file is treated as private.
Suggested fix
Add cloud-config-bundle-cache.json to PRIVATE_ENTRY_NAMES. This is a narrower case than the fix this issue asks for. The general fix should also not default to linking: a new per-account file is safer kept local than shared.
Windows reproduction: split WAL files can lose committed writes
Adding a data-loss reproduction for the sidecar-only variant already described here.
Environment: Windows 11 x64 (10.0.26200), T3 Code Nightly 0.0.46-nightly.20261013.3040, Codex CLI 0.162.1, Node 24.14.0. Two Codex accounts were configured with a shared home and a shadow home.
In addition to provider-creation conflicts (db-backups in this installation), archived Codex databases failed SQLite integrity checks. Codex's retained logs explicitly reported corruption in thread_history_1.sqlite. The precise historical corruption timing was not captured, so the fixture below establishes a reproducible unsafe write mechanism rather than proving the origin of every damaged page.
Reproduction
A fixture invoking T3's actual materializeCodexShadowHome implementation from the installed server reproduced this sequence:
Create and close a WAL-mode SQLite database in the shared home. At materialization time its -wal and -shm files do not exist.
Materialize the shadow. T3 links the base database, but there are no sidecars to link.
Open the shared database and commit a row, keeping that connection open.
Open the same physical database through the shadow path and commit a different row.
Close both connections and reopen the shared database.
Both inserts succeed, but only one of the two committed rows remains. The shadow connection uses its own regular WAL/SHM files for the linked base database. This does not require overlapping transactions, a crash, an authentication failure, or model inference.
Here is a standalone Node reproduction of the resulting file layout. Run as an .mjs file on Windows with file-symlink support. It uses only a fresh temporary directory:
import{DatabaseSync}from'node:sqlite';import{mkdtempSync,mkdirSync,symlinkSync}from'node:fs';import{tmpdir}from'node:os';import{join}from'node:path';importassertfrom'node:assert/strict';constroot=mkdtempSync(join(tmpdir(),'t3-shadow-wal-'));constshared=join(root,'shared');constshadow=join(root,'shadow');mkdirSync(shared);mkdirSync(shadow);constsharedDb=join(shared,'state_5.sqlite');constshadowDb=join(shadow,'state_5.sqlite');constseed=newDatabaseSync(sharedDb);seed.exec('PRAGMA journal_mode=WAL; CREATE TABLE writes (id INTEGER PRIMARY KEY)');seed.close();// This is the database layout materializeCodexShadowHome creates when sidecars are absent.symlinkSync(sharedDb,shadowDb,'file');consta=newDatabaseSync(sharedDb);a.exec('INSERT INTO writes VALUES (1)');constb=newDatabaseSync(shadowDb);b.exec('INSERT INTO writes VALUES (2)');b.close();a.close();constcheck=newDatabaseSync(sharedDb);constrows=check.prepare('SELECT id FROM writes ORDER BY id').all();check.close();console.log(rows);assert.equal(rows.length,2,'A committed write was lost');
Observed: the assertion fails with 1 !== 2. The same write check with two independent physical provider databases retains both writes. The actual-T3 fixture also retained 1/2 with the shadow layout and 2/2 with independent homes.
An acceptance test should cover a linked base database whose sidecars were absent during materialization, then verify both committed writes survive. Handling an existing regular sidecar conflict alone would not establish database safety. Independent direct homes were used as the local workaround, preserving the account credentials and available rollouts; this does not claim to preserve the intended ongoing shared-history behavior of shadow homes.
Reproduction and diagnosis assisted by GPT-6.1-Sol in Codex desktop.
Follow-up to my earlier report: the providers became unavailable again on Windows, but this time with a different shadow-home failure mode.
Environment
T3 Code: 0.0.46-nightly.20261013.3066 (desktop, Nightly)
Codex CLI: 0.162.1 (verified with the CLI configured in T3)
Windows 11 Pro 25H2, build 26200.9457, x64
Three enabled Codex account instances sharing one homePath (<user-home>/.codex), each with a separate shadowHomePath (<t3-userdata>/providers/codex/<account-instance>/shadow). Paths and account identifiers are placeholders.
All three instances retained an explicit sqlite_home override pointing to the shared Codex directory, with cli_auth_credentials_store="file".
New findings
The explicit sqlite_home override pointing to the shared Codex directory was still configured on all three affected providers.
The initial failure was a CodexShadowHomeFileSystemError wrapping EPERM: operation not permitted, symlink. T3 attempted to link a newly present, non-runtime configuration backup from the shared home into each shadow home. That single file blocked initialization of all three providers.
Unlike the earlier regular-file conflicts, inspection found no conflicting regular shadow entries at that point; the required links were missing.
After relocating the backup outside the mirrored directory and reloading the providers, two authenticated successfully. The remaining provider then failed to create links for memories_1.sqlite-shm and memories_1.sqlite-wal.
A direct attempt to create those missing links without administrator privileges returned Windows error 1314: a required privilege is not held by the client. Creating only those two links with administrator permission and reloading the remaining provider restored it.
Verification and implication
All three affected providers subsequently showed Authenticated in T3, and the provider connection probes succeeded. The backup was preserved with its contents verified unchanged.
The sqlite_home override alone did not prevent T3's shadow-home initialization from requiring links for SQLite sidecars and other shared-home entries. This is a related Windows link-creation/permissions failure, distinct from the existing regular-file conflict reported earlier. It may warrant separate tracking at maintainers' discretion.
This was a local recovery, not a verified permanent fix. No database-integrity testing was performed, and I am not claiming data loss or corruption in this installation. Personal paths, account details, and identifiers are omitted.
Follow-up: this recurred on newer versions after the previous successful repair.
Environment
T3 Code: 0.1.1-nightly.20261019.3373 (desktop, Nightly)
Codex CLI: 0.163.0
Windows, x64
Three enabled Codex account instances sharing one Codex home, each with a separate shadow home. Account names, identifiers, and personal paths are omitted.
All three still had an explicit sqlite_home override pointing to the shared Codex directory.
Observed recurrence
All three providers failed shadow-home initialization on goals_1.sqlite-shm, with CodexShadowHomeEntryConflictError reporting that the entry already existed and was not a symlink.
Inspection found 12 regular SQLite sidecar files across the three shadow homes:
goals_1.sqlite-shm and goals_1.sqlite-wal in all three.
thread_history_1.sqlite-shm and thread_history_1.sqlite-wal in two.
memories_1.sqlite-shm and memories_1.sqlite-wal in the remaining one.
The two regular thread-history WAL files were nonempty: 4,152,992 and 4,144,752 bytes. Links for the shared project-metadata-locks directory were also missing in all three shadow homes, but this directory was not established as a failure trigger; initialization failed on the SQLite conflict first.
Recovery verification
The repair preserved the 12 regular sidecar files, restored 19 conflicting or missing links in total, and reloaded the affected providers. Subsequent shadow-home initialization and provider connection probes succeeded. A follow-up filesystem inspection found no remaining regular SQLite sidecar conflicts or missing shared-entry links at that check.
This confirms recurrence after an earlier successful link repair, with the explicit shared sqlite_home configuration still present. It does not establish when or why each sidecar became a regular file, nor prove that the override was honored by every database operation. Restoring the links remains a recovery workaround, not a verified permanent fix.
No database-integrity testing was performed, and no data loss or corruption is claimed for this installation. No raw logs, credentials, or account identifiers are attached.
Triage inspected current main at b5a226e49c and all six comments. Runtime reproduction was not performed. The general reconciliation requested here changes which files the multi-account authentication overlay shares versus keeps private; the reported per-account cloud configuration cache makes that boundary material. This reaches the automated triage rule requiring maintainer review for authentication/credential changes. Leaving this issue open for Julius; no fix or data migration was attempted.
Reproduced on Linux with Codex 0.163.0 and main 3b95e7831b. Started the real dev server with disposable shared/shadow Codex homes and two provider instances. Initial materialization succeeded; Codex created regular runtime entries in both homes. After restarting, shadow provider creation failed with CodexShadowHomeEntryConflictError on the first conflicting entry, .tmp. Both homes also contain regular queue_1.sqlite databases. No account credentials were required for this reproduction.
Windows data from three machines on 0.1.2-nightly.20261022.3541 (same commit as v0.1.2), Codex CLI 0.163.0. This adds two things to the thread. The first is the mechanism that keeps recreating the regular sidecars. The second is a reproduction showing that keeping the regular sidecars in place, which is what #23472 does, loses committed writes on Windows.
Exact error (Limerence, Windows 11, 2026-10-22T20:59:20Z, after a T3 restart)
ProviderInstanceRegistry.buildEntry ERROR "Failed to create provider instance" {"instanceId":"codex","driver":"codex","detail":"Cannot create Codex shadow home entry 'memories_1.sqlite-shm' because 'C:\\Users\\<user>\\.codex-t3\\hub-noauth\\memories_1.sqlite-shm' already exists and is not a symlink."}
CodexShadowHomeEntryConflictError at CodexHomeLayout.ensureSymlink (binCli-oeMvh2hs.mjs:182516:79)
The same machine failed on goals_1.sqlite-shm after the restart at 19:15Z. The instance was down from 20:59:18Z to 21:04:07Z. Every T3 restart kills Codex and can cause this, so a setup that restarts T3 after each update hits it repeatedly.
Files found in the shadow home. In every case the base <db>.sqlite was a link into ~/.codex and the sidecars were regular files:
Machine
File
Size
Limerence, 19:15Z
goals_1.sqlite-shm / -wal
32768 / 0
Limerence, 19:15Z
memories_1.sqlite-shm / -wal
32768 / 0
Limerence, 20:59Z
memories_1.sqlite-shm / -wal
32768 / 0
Amicus (Windows), live while running
thread_history_1.sqlite-shm / -wal
32768 / 4,169,472
Amicus, live while running
memories_1.sqlite-shm / -wal
32768 / 0 (recreated within minutes of being removed)
Why the files keep coming back
Linux: SQLite's unix VFS resolves the symlink before naming -wal/-shm, so the sidecars land next to the real database. I tested this with node:sqlite (SQLite 3.53.1): no regular files appear in the shadow home and no writes are lost. The sidecar-only variant therefore occurs on Windows only.
Windows: the win32 VFS names the sidecars from the path it was given (SQLite 3.50.4 and 3.53.4 tested).
If T3 materialized while the shared home had no <db>-wal/-shm, nothing is linked, and Codex creates regular sidecars in the shadow home. From then on its writes go to its own WAL. Two committed rows leave one row in the shared DB, which reproduces the 2026-10-13 comment above.
If the sidecar links do exist, they survive a killed process. But when the shadow Codex is the last connection and closes cleanly, SQLite deletes -wal/-shm by the shadow path. That removes T3's links, not the files they point to. The next open from the shadow creates regular files again. This explains the sidecar links disappearing between restarts.
Keeping the regular sidecars (#23472) loses newer writes
Below is a standalone node:sqlite script using a fresh temp dir. On Windows it uses a file symlink, as T3 does. On Linux a hard link gives the same SQLite file naming.
// A regular shadow -wal left beside a linked database (what PR #23472 keeps in place) erases// newer committed writes the next time Codex opens the database through the shadow path.// Windows: file symlink, as T3 creates. Linux: a hard link gives the same SQLite file naming// (SQLite resolves symlinks there). Fresh temp dir only. Run: node upstream-stale-wal-repro.mjsimport{DatabaseSync}from'node:sqlite';import{mkdtempSync,mkdirSync,symlinkSync,linkSync,readdirSync,lstatSync}from'node:fs';import{tmpdir}from'node:os';import{join}from'node:path';import{spawnSync}from'node:child_process';if(process.argv[2]==='--commit-and-die'){newDatabaseSync(process.argv[3]).exec(`INSERT INTO t(who) VALUES ('${process.argv[4]}')`);process.exit(0);// T3 restart kills Codex: no close, the shadow WAL keeps its committed frame}constroot=mkdtempSync(join(tmpdir(),'stale-wal-'));constshared=join(root,'codex'),shadow=join(root,'codex-t3','hub');mkdirSync(shared);mkdirSync(shadow,{recursive: true});constreal=join(shared,'goals_1.sqlite'),link=join(shadow,'goals_1.sqlite');constrows=(p)=>{constd=newDatabaseSync(p);constr=d.prepare('SELECT who FROM t ORDER BY id').all().map((x)=>x.who);d.close();returnr;};constseed=newDatabaseSync(real);seed.exec("PRAGMA journal_mode=WAL; CREATE TABLE t (id INTEGER PRIMARY KEY, who TEXT); INSERT INTO t(who) VALUES ('seed')");seed.close();if(process.platform==='win32')symlinkSync(real,link,'file');elselinkSync(real,link);// 1. Shadow-home Codex commits a row, then T3 restarts and kills it.spawnSync(process.execPath,[process.argv[1],'--commit-and-die',link,'shadow-before-restart'],{stdio: 'inherit'});console.log('shadow home after kill:',readdirSync(shadow).map((n)=>`${n}:${lstatSync(join(shadow,n)).isSymbolicLink() ? 'link' : 'file '+lstatSync(join(shadow,n)).size}`).join(' '));// 2. While the shadow provider is down, the main Codex commits and closes cleanly.constmain=newDatabaseSync(real);main.exec("INSERT INTO t(who) VALUES ('main-while-shadow-down')");main.close();console.log('real DB before the shadow reopens:',rows(real));// 3. T3 keeps the regular sidecars (PR #23472) and the shadow Codex opens the DB again.console.log('shadow sees:',rows(link));console.log('real DB after the shadow reopened and closed:',rows(real));
Output on Linux (hard link; node 24.18, SQLite 3.53.1):
shadow home after kill: goals_1.sqlite:file 8192 goals_1.sqlite-shm:file 32768 goals_1.sqlite-wal:file 4152
real DB before the shadow reopens: [ 'seed', 'main-while-shadow-down' ]
shadow sees: [ 'seed', 'shadow-before-restart' ]
real DB after the shadow reopened and closed: [ 'seed', 'shadow-before-restart' ]
Output on Windows (file symlink):
shadow home after kill: goals_1.sqlite:link goals_1.sqlite-shm:file 32768 goals_1.sqlite-wal:file 4152
real DB before the shadow reopens: [ 'seed', 'main-while-shadow-down' ]
shadow sees: [ 'seed', 'shadow-before-restart' ]
real DB after the shadow reopened and closed: [ 'seed', 'shadow-before-restart' ]
(node v24.21.0, Windows, file symlink)
The 4152-byte shadow WAL (a 32-byte header plus one frame) holds one committed transaction. The process that wrote it was killed before checkpointing. Afterwards, the main Codex commits and closes cleanly. When the shadow opens the database again, SQLite recovers its own stale WAL, and the next checkpoint writes those pages over the newer ones. integrity_check still reports ok, so the loss is silent. Two other options are also unsafe. Replacing the regular sidecars with links drops the shadow's unapplied commits. Checkpointing the shadow WAL first is safe only if the real database has not changed since that WAL began.
What we run locally until this is fixed: a pre-launch sweep, run before T3 starts.
For each regular shadow sidecar beside a linked database, it counts committed frames on scratch copies.
If there are none, it moves the files.
If there are some, it applies them through the shadow path only when that provably adds rows: the real DB has no unapplied WAL frames of its own, and "real DB + shadow WAL" passes integrity_check and still contains every row of the real DB.
Otherwise it moves the files aside without applying them and flags the rows.
It also moves away a shared <db>-wal whose links were deleted, if every frame in it is already in the database. Otherwise the next open would replay it over newer pages.
None of this addresses the root cause. On Windows the shadow-home Codex should probably not open shared SQLite databases through a link at all. Opening them by their real path, for example through Codex's sqlite_home or CODEX_SQLITE_HOME pointing at the shared home, would give one WAL and one lock table per database. An earlier comment reports sidecars returning even with sqlite_home set, so that would need checking against the Codex version T3 runs.
This tracker covers the materializeCodexShadowHome conflict — a regular shadow entry disabling that instance. #24486 covers what happens when materialization succeeds anyway: the SQLite base file is shared while -wal/-shm stay shadow-local, so the database is corrupted and the defaultcodex provider (no shadow home) is the one that ends up failing with Codex App Server process exited with code 1 / os error 32, on a rebuild loop.
Relevant to this issue's acceptance criterion "SQLite families such as the base DB, WAL, and SHM are handled together": the implementation that addressed it here, #19861, was closed on 2026-10-19 without merging, so that criterion currently has nothing in flight.
Worth keeping distinct because an allowlist or self-heal change satisfies this tracker while leaving the WAL split intact — verified locally on 0.1.3-nightly.20261023.3553: with every conflicting shadow entry treated as replaceable, codex-2/codex-3 report ready and no CodexShadowHomeEntryConflictError is logged, while state_5.sqlite keeps being rebuilt into db-backups\sqlite-* every few minutes.
I saw the same shadow-home conflict with memories.lock.
Environment: T3 Code Desktop 0.1.4-nightly.20261028.3824, local server on macOS arm64, Codex CLI 0.165.0.
Observed: A secondary Codex provider was disabled because memories.lock existed as a regular file in both the shared home and the shadow home. Both files were empty. T3 reported that the shadow entry existed and was not a symlink.
Source: At commit eb751fa0730d6a51d56547cb7fcaf4822a7e0e3b, shadow-home setup treats memories as local, but does not classify memories.lock as local or replaceable. It attempts to link the shared entry and rejects the regular shadow file.
Workaround confirmed: Moved the shadow lock file aside, then disabled and enabled the provider. The provider returned.
Environment: T3 Code Desktop nightly 0.1.8-nightly.20261108.4380 on macOS, connected to a remote Linux server running the same version. Codex CLI 0.167.0.
Failure: Two consecutive runs failed before Codex started:
Cannot create Codex shadow home entry 'auth.json.lock' because '<shadow-home>/auth.json.lock' already exists and is not a symlink.
Diagnosis: Empty regular auth.json.lock files existed in both shared and shadow homes. CodexHomeLayout.ts classifies auth.lock as private but omits auth.json.lock; materialization therefore attempts to link it and rejects the regular shadow copy. The original file-creation event was not captured.
Reproduction: Create empty regular auth.json.lock files in shared and shadow homes, then materialize the shadow home.
Recovery: After confirming neither lock was open or held, backed up the shadow lock and replaced it with the expected symlink. No credentials were changed. Codex login status succeeds; no remaining file conflicts. An authenticated model turn and long-term recurrence remain untested.
The newer nightly 0.1.8-nightly.20261109.4392 retains the same classification. Related: #8578.
Prepared by GPT-6.1-Sol through the Codex harness in T3 Code.
Still reproduces on the stable 0.1.8 release with Codex CLI 0.167.1, on macOS arm64 and Windows x64. Two more entries that disabled a shadow-home instance:
macOS: memories.lock. An empty (0-byte) regular file existed in both the shared home and the shadow home. In 0.1.8, SHADOW_LOCAL_ENTRY_NAMES is log, memories, tmp, .DS_Store, so memories stays local but its sibling memories.lock is linked, and ensureSymlink rejects the shadow copy:
Driver 'codex' failed to create instance: Cannot create Codex shadow home entry 'memories.lock' because '<shadow>/memories.lock' already exists and is not a symlink.
Workaround used: move the conflicting entries out of the shadow home. The next provider settings change triggers a reconcile, which recreates the links. Without that manual step, the instance stays disabled, and the UI shows only the error text.
#32058 (move the real entry into .t3-shadow-conflicts/ and link it) would cover both cases. Whichever fix lands, an empty *.lock beside a shadow-local entry (memories.lock next to memories) is probably better kept shadow-local than moved and shared.
Still reproduces on stable 0.1.9 (desktop app, macOS arm64) with Codex CLI 0.167.2, filename auth.json.lock.
Driver 'codex' failed to create instance: Cannot create Codex shadow home entry 'auth.json.lock' because '~/.codex_contact/auth.json.lock' already exists and is not a symlink.
Sequence: Codex created an empty regular auth.json.lock in the shadow home (~/.codex_contact, mtime matches its auth.json). Later, Codex created another one in the shared home ~/.codex. On the next materialization, the shadow instance was disabled. Its provider status cache stopped updating within a minute of the shared lock appearing.
Source (v0.1.9 and current main):PRIVATE_ENTRY_NAMES in CodexHomeLayout.ts is still auth.json, auth.lock, models_cache.json. auth.json.lock is the lock for the private auth.json, so it should be private rather than linked. #23428 (auth-like entries private, from #8578) looks like it would cover this; it's still unmerged.
Workaround: moved the empty shadow auth.json.lock aside while nothing held it open (checked with lsof). T3 then links it to the shared lock, so both accounts share one auth lock.
Investigated with t3 triage using Claude Code (Claude Opus 5.5).
This comment was investigated, written, and posted by Codex (GPT-6-Astra), acting on behalf of @loris-olsem at their request.
Confirmed recurrence on Windows x64, T3 desktop/local server 0.1.10-nightly.20261114.4669, Codex 0.169.0, on 2026-11-14. This is the same goals_1.sqlite-shm conflict documented in #20261 (closed into this issue), now on a managed “Connect with ChatGPT” instance.
The affected instance had config: { "setupMode": "managed" }; its shadow home was automatically assigned beneath <T3_DATA>/providers/codex/<instance>/shadow. The default Codex instance was disabled. A primary Codex conversation and Codex workers delegated from a Claude conversation were affected.
Observed sequence (UTC):
16:19:57: reopening a Codex conversation failed with the error below.
16:20:19: provider shadow-home materialization failed with the same error.
16:20:50–16:20:52: a delegated worker repeatedly failed to open its provider session on the same conflict.
By inspection later, the database, WAL and SHM entries were symlinks, and conversations were progressing again. The action that changed these entries was not captured by this investigation.
The user still reported broken provider settings/model selection after conversations resumed. The screenshot showed authenticated ChatGPT credentials, “Could not check Codex right now. Retry, or reconnect in provider settings.” and 0 models.
At 16:29:37, the latest backend check was successful. A subsequent server.getConfig read returned status: "ready" and 8 models. Existing workspace snapshots included modelsPending: true.
At 16:31:07, an explicit server.refreshProviders request with {instanceId, fresh: true, refreshModels: true} succeeded. The server configuration subscription also returned ready/8 models. Fresh workspace requests subsequently cleared the pending flags. The user confirmed provider settings and the model picker worked again, without another login or reinstall.
Sanitized error:
CodexShadowHomeEntryConflictError:
Cannot create Codex shadow home entry 'goals_1.sqlite-shm' because
'<T3_DATA>/providers/codex/<instance>/shadow/goals_1.sqlite-shm'
already exists and is not a symlink.
at CodexHomeLayout.ensureSymlink
at materializeCodexShadowHome
Installed-code findings:
CodexHomeLayout.ensureSymlink still rejects a regular shadow entry unless it is in REPLACEABLE_SHARED_RUNTIME_ENTRIES. That set contains mcp-oauth-locks, thread-writer-locks, and .sqlite-maintenance.lock, but no SQLite sidecars.
The managed provider check catches failures and constructs a snapshot with models: [], retained authenticated status where saved credentials permit it, and the generic reconnect message. This masks the actionable filesystem error. The registry also has model-retention logic, so this is not a claim that every failed check always clears the final published catalog.
mergeProviderSnapshot marks existing workspace catalogs pending when the machine model list changes. The precise reason the open UI did not recover earlier was not isolated; no client update-stream capture was available before recovery.
This adds current-version evidence and a misleading recovery-message/UI symptom to the existing issue, rather than proposing deletion/relinking of live SQLite files. #24486 explains why database/WAL/SHM ownership must be handled together. No database corruption was established here, and no new isolated reproduction was run.
Earlier Responses requests also returned 401 “Missing bearer … in header”, and one provider stream closed during compaction. Those are separate observations; this investigation does not establish that the shadow-home conflict caused either, or that the token-catalog issue in #33701 is the same cause.
Prepared by Codex from local logs, the installed bundle, and read-back through T3's API; recovery was confirmed by the user. No credentials, account identifiers, project contents, or raw logs are attached.
Two more real-world triggers for this, seen after updating to nightly 0.1.12-nightly.20261120.5009 (multi-account layout, one shadowHomePath per account under ~/.codex-t3/<account>/):
.sandbox_migration (Windows). Codex had written a regular 3-byte file (v1\n) into two account homes days earlier (Nov 12 and Nov 18). After the update, both providers were disabled at startup:
Driver 'codex' failed to create instance: Cannot create Codex shadow home entry '.sandbox_migration' because '<home>\.codex-t3\<account>\.sandbox_migration' already exists and is not a symlink.
auth.json.lock (macOS). A zero-byte regular auth.json.lock from Nov 15 sat in two account homes. Both providers were disabled with the same error naming auth.json.lock.
In both cases nothing held the file. Renaming it aside and then toggling the provider off and on in Settings brought the provider back. A T3 restart alone doesn't help until the file is moved, and toggling is needed because the instance error is cached from startup.
So besides newly introduced runtime entries, any pre-existing regular file at a path the shadow home now wants to link (markers and stale locks that Codex leaves behind) disables the provider after an update. Adopting or ignoring stale regular entries, or at least naming the remedy in the error, would avoid a silent loss of the provider.
One more filename: session_index.jsonl (plus session_index.jsonl.lock), on T3 0.1.11 (Linux server, t3 serve), Codex CLI 0.171.0.
Driver 'codex' failed to create instance: Cannot create Codex shadow home entry 'session_index.jsonl' because '<shadow-home>/session_index.jsonl' already exists and is not a symlink.
Sequence: T3 built the shadow home before Codex had ever created session_index.jsonl in the shared home. Codex later created it in the shared home, and separately created a real file in the shadow home the first time that account named a thread. The next T3 restart disabled the shadow-home provider.
Why this case matters: Unlike the lock, -shm/-wal and cache files reported above, this file has content: Codex thread names, one JSON line per thread ID. The shadow copy held entries that weren't in the shared file, so deleting it loses those thread names. Recovery here meant appending the shadow-only lines to the shared file (deduplicated by id), moving the shadow session_index.jsonl and .lock aside, and restarting T3. Any automatic reconciliation should merge files like this one rather than discard the shadow copy.
Activity
[-][Bug]: Codex 0.147 queue DB disables shadow-home provider instances[/-][+][Bug]: New Codex runtime entries can disable existing shadow-home providers[/+]EwenGG commentedon Aug 20, 2026
I can confirm this issue on Windows, with an additional sidecar-only variant that may be relevant to the proposed fix in #7201.
Environment
0.0.34-nightly.20260820.11410.148.010.0.26200, x64Sanitized configuration:
{ "driver": "codex", "enabled": true, "config": { "homePath": "C:\\Users\\<user>\\.codex", "shadowHomePath": "C:\\Users\\<user>\\.codex_p" } }Observed behavior
This has recurred across several recent T3 Code Nightly and Codex updates.
On startup or provider refresh, the secondary Codex provider is disabled during
materializeCodexShadowHome. T3 encounters a regular SQLite runtime sidecar in the shadow home where it expects a symbolic link, then aborts provider creation.Exact error
The corresponding server trace reports:
Previous occurrences on the same machine failed on other members of the same class of runtime files:
Because materialization stops at the first conflict, the filename displayed by T3 does not represent the complete set of conflicting entries.
Shadow-home state at failure time
A complete inspection of the shadow-home root found eight regular SQLite sidecar files:
logs_2.sqlite-shmlogs_2.sqlite-walmemories_1.sqlite-shmmemories_1.sqlite-walqueue_1.sqlite-shmqueue_1.sqlite-walstate_5.sqlite-shmstate_5.sqlite-walThe problem was therefore not limited to
queue_1.sqlite.Importantly, the corresponding base database entries were still symbolic links to the shared Codex home:
In this occurrence, the divergence was specifically:
This is slightly different from the original #5817 reproduction, where the shadow base database itself is described as becoming a regular file.
Recurrence evidence
Retained local logs show repeated failures on at least two consecutive days:
memories_1.sqlite-shmlogs_2.sqlite-shmqueue_1.sqliteThe problem has returned after multiple manual recoveries and subsequent updates or restarts. It is not an isolated stale file left by a single interrupted process.
Different SQLite families become affected at different times. Some sidecars already existed from the previous day, while others were created or rewritten during the next T3/Codex run.
Impact
Recovery confirmation
For diagnostic purposes, I backed up and moved all eight regular
*.sqlite-waland*.sqlite-shmfiles out of the shadow home. I did not modify the privateauth.jsonormodels_cache.jsonfiles.I then disabled and re-enabled only the affected provider instance.
After rematerialization:
This immediately restored the provider, confirming that the regular SQLite sidecars directly caused provider creation to fail.
However, the same class of conflict has returned after later updates or runs, so this procedure is only a temporary recovery.
Relation to PR #7201
PR #7201 appears to target the same underlying class of failure:
#7201
Its stated goal—keeping newly created Codex SQLite state shadow-local and treating a base database plus its WAL/SHM sidecars as one family—matches the recurring behavior observed here.
However, my captured state includes a sidecar-only divergence: the shadow base
.sqliteentry remained a symbolic link while its-waland-shmentries were regular files.The PR description and diff appear to select shadow-local ownership when the shadow base database is already a regular file. I cannot confirm whether it also covers the observed case where only the WAL/SHM members have become regular files.
This Windows reproduction may therefore be useful for validating #7201 against both forms:
I am not proposing a separate implementation here. I am documenting the additional observed state so that the existing fix can be evaluated against the complete failure mode.
tgangso commentedon Oct 7, 2026
Adding updated Windows findings here as requested when #17005 was closed as a duplicate.
Environment
0.0.46-nightly.20261007.27870.161.0Observed failure
Three Codex providers failed to initialize with this sanitized error:
Inspection confirmed the sidecar-only state already described in this issue: base SQLite databases were symlinks to the shared home, while some
-shmand-walfiles were regular files in the shadow homes. Some WAL files were nonempty.In the installed build,
materializeCodexShadowHomeattempts to link shared-home entries, andensureSymlinkrejects these existing regular files. The initial creation of the conflicting files was not captured; no fresh-install reproduction or repository regression test was run.Workaround and verification
The conflicting files were backed up and moved out of the shadow homes, allowing T3 to recreate the links. Each affected provider's launch arguments were also configured to set
sqlite_homeexplicitly to the shared Codex directory.After T3 reloaded the settings, all three provider connection probes succeeded. No regular SQLite sidecar conflicts remained at that check. Long-term recurrence has not yet been tested.
This confirms the failure on the versions above and records the observed recovery. It is not a recommendation to delete SQLite sidecars or a claim that a permanent upstream fix has been verified. Related shared-directory approach: #9229.
dustenhubbard commentedon Oct 8, 2026
Another entry for this issue, from Codex 0.161.0:
cloud-config-bundle-cache.json. This one should not be linked, either.Environment
0.0.46-nightly.20261007.2774(desktop)0.161.0~/.codex, and a second instance withshadowHomePathset to~/.codex-t3/workWhat happened
After a T3 restart, the second instance showed only "Disabled" in Settings → Providers, with its toggle still on. Its status cache had stopped updating at the restart. The settings were unchanged.
cloud-config-bundle-cache.jsonexisted as a regular file in both the shared home and the shadow home. In the installed build,PRIVATE_ENTRY_NAMESisauth.jsonandmodels_cache.json, somaterializeCodexShadowHometries to link this file andensureSymlinkrejects the regular copy. I did not find the error text in the server trace. I am going by the file state and the code.Why linking is the wrong fix for this file
The file is per-account. It holds
chatgpt_user_id,account_id, and the workspace's signed enterpriseconfig_tomlandrequirements_toml, with a one-hour expiry. If it were shared, one account could pick up another account's workspace policy. It belongs withauth.jsonandmodels_cache.json.Linking also does not last. I deleted the shadow copy and turned the provider off and on. The provider came back, but within seconds there was a regular file in the shadow home again, and the shared copy had not changed. So the next restart would disable the provider again.
Workaround
A small job deletes the shadow copy every two minutes, so a restart does not find one. Codex fetches the bundle again when it needs it. This only matters until the file is treated as private.
Suggested fix
Add
cloud-config-bundle-cache.jsontoPRIVATE_ENTRY_NAMES. This is a narrower case than the fix this issue asks for. The general fix should also not default to linking: a new per-account file is safer kept local than shared.TimeAndLocation commentedon Oct 13, 2026
Windows reproduction: split WAL files can lose committed writes
Adding a data-loss reproduction for the sidecar-only variant already described here.
Environment: Windows 11 x64 (
10.0.26200), T3 Code Nightly0.0.46-nightly.20261013.3040, Codex CLI0.162.1, Node24.14.0. Two Codex accounts were configured with a shared home and a shadow home.In addition to provider-creation conflicts (
db-backupsin this installation), archived Codex databases failed SQLite integrity checks. Codex's retained logs explicitly reported corruption inthread_history_1.sqlite. The precise historical corruption timing was not captured, so the fixture below establishes a reproducible unsafe write mechanism rather than proving the origin of every damaged page.Reproduction
A fixture invoking T3's actual
materializeCodexShadowHomeimplementation from the installed server reproduced this sequence:-waland-shmfiles do not exist.Both inserts succeed, but only one of the two committed rows remains. The shadow connection uses its own regular WAL/SHM files for the linked base database. This does not require overlapping transactions, a crash, an authentication failure, or model inference.
Here is a standalone Node reproduction of the resulting file layout. Run as an
.mjsfile on Windows with file-symlink support. It uses only a fresh temporary directory:Observed: the assertion fails with
1 !== 2. The same write check with two independent physical provider databases retains both writes. The actual-T3 fixture also retained1/2with the shadow layout and2/2with independent homes.The relevant main-branch code still enumerates only entries currently present in the shared home: CodexHomeLayout.ts. SQLite explains why multiple names and separate journals/WAL files are unsafe.
An acceptance test should cover a linked base database whose sidecars were absent during materialization, then verify both committed writes survive. Handling an existing regular sidecar conflict alone would not establish database safety. Independent direct homes were used as the local workaround, preserving the account credentials and available rollouts; this does not claim to preserve the intended ongoing shared-history behavior of shadow homes.
Reproduction and diagnosis assisted by GPT-6.1-Sol in Codex desktop.
tgangso commentedon Oct 13, 2026
Follow-up to my earlier report: the providers became unavailable again on Windows, but this time with a different shadow-home failure mode.
Environment
0.0.46-nightly.20261013.3066(desktop, Nightly)0.162.1(verified with the CLI configured in T3)26200.9457, x64homePath(<user-home>/.codex), each with a separateshadowHomePath(<t3-userdata>/providers/codex/<account-instance>/shadow). Paths and account identifiers are placeholders.sqlite_homeoverride pointing to the shared Codex directory, withcli_auth_credentials_store="file".New findings
sqlite_homeoverride pointing to the shared Codex directory was still configured on all three affected providers.CodexShadowHomeFileSystemErrorwrappingEPERM: operation not permitted, symlink. T3 attempted to link a newly present, non-runtime configuration backup from the shared home into each shadow home. That single file blocked initialization of all three providers.memories_1.sqlite-shmandmemories_1.sqlite-wal.Verification and implication
All three affected providers subsequently showed Authenticated in T3, and the provider connection probes succeeded. The backup was preserved with its contents verified unchanged.
The
sqlite_homeoverride alone did not prevent T3's shadow-home initialization from requiring links for SQLite sidecars and other shared-home entries. This is a related Windows link-creation/permissions failure, distinct from the existing regular-file conflict reported earlier. It may warrant separate tracking at maintainers' discretion.This was a local recovery, not a verified permanent fix. No database-integrity testing was performed, and I am not claiming data loss or corruption in this installation. Personal paths, account details, and identifiers are omitted.
tgangso commentedon Oct 19, 2026
Follow-up: this recurred on newer versions after the previous successful repair.
Environment
0.1.1-nightly.20261019.3373(desktop, Nightly)0.163.0sqlite_homeoverride pointing to the shared Codex directory.Observed recurrence
All three providers failed shadow-home initialization on
goals_1.sqlite-shm, withCodexShadowHomeEntryConflictErrorreporting that the entry already existed and was not a symlink.Inspection found 12 regular SQLite sidecar files across the three shadow homes:
goals_1.sqlite-shmandgoals_1.sqlite-walin all three.thread_history_1.sqlite-shmandthread_history_1.sqlite-walin two.memories_1.sqlite-shmandmemories_1.sqlite-walin the remaining one.The two regular thread-history WAL files were nonempty: 4,152,992 and 4,144,752 bytes. Links for the shared
project-metadata-locksdirectory were also missing in all three shadow homes, but this directory was not established as a failure trigger; initialization failed on the SQLite conflict first.Recovery verification
The repair preserved the 12 regular sidecar files, restored 19 conflicting or missing links in total, and reloaded the affected providers. Subsequent shadow-home initialization and provider connection probes succeeded. A follow-up filesystem inspection found no remaining regular SQLite sidecar conflicts or missing shared-entry links at that check.
This confirms recurrence after an earlier successful link repair, with the explicit shared
sqlite_homeconfiguration still present. It does not establish when or why each sidecar became a regular file, nor prove that the override was honored by every database operation. Restoring the links remains a recovery workaround, not a verified permanent fix.No database-integrity testing was performed, and no data loss or corruption is claimed for this installation. No raw logs, credentials, or account identifiers are attached.
juliusmarminge commentedon Oct 22, 2026
Triage inspected current main at b5a226e49c and all six comments. Runtime reproduction was not performed. The general reconciliation requested here changes which files the multi-account authentication overlay shares versus keeps private; the reported per-account cloud configuration cache makes that boundary material. This reaches the automated triage rule requiring maintainer review for authentication/credential changes. Leaving this issue open for Julius; no fix or data migration was attempted.
juliusmarminge commentedon Oct 22, 2026
Reproduced on Linux with Codex 0.163.0 and main 3b95e7831b. Started the real dev server with disposable shared/shadow Codex homes and two provider instances. Initial materialization succeeded; Codex created regular runtime entries in both homes. After restarting, shadow provider creation failed with CodexShadowHomeEntryConflictError on the first conflicting entry, .tmp. Both homes also contain regular queue_1.sqlite databases. No account credentials were required for this reproduction.
WhiteWarrior625 commentedon Oct 22, 2026
Windows data from three machines on
0.1.2-nightly.20261022.3541(same commit as v0.1.2), Codex CLI0.163.0. This adds two things to the thread. The first is the mechanism that keeps recreating the regular sidecars. The second is a reproduction showing that keeping the regular sidecars in place, which is what #23472 does, loses committed writes on Windows.Exact error (Limerence, Windows 11, 2026-10-22T20:59:20Z, after a T3 restart)
The same machine failed on
goals_1.sqlite-shmafter the restart at 19:15Z. The instance was down from 20:59:18Z to 21:04:07Z. Every T3 restart kills Codex and can cause this, so a setup that restarts T3 after each update hits it repeatedly.Files found in the shadow home. In every case the base
<db>.sqlitewas a link into~/.codexand the sidecars were regular files:goals_1.sqlite-shm/-walmemories_1.sqlite-shm/-walmemories_1.sqlite-shm/-walthread_history_1.sqlite-shm/-walmemories_1.sqlite-shm/-walWhy the files keep coming back
-wal/-shm, so the sidecars land next to the real database. I tested this withnode:sqlite(SQLite 3.53.1): no regular files appear in the shadow home and no writes are lost. The sidecar-only variant therefore occurs on Windows only.<db>-wal/-shm, nothing is linked, and Codex creates regular sidecars in the shadow home. From then on its writes go to its own WAL. Two committed rows leave one row in the shared DB, which reproduces the 2026-10-13 comment above.-wal/-shmby the shadow path. That removes T3's links, not the files they point to. The next open from the shadow creates regular files again. This explains the sidecar links disappearing between restarts.Keeping the regular sidecars (#23472) loses newer writes
Below is a standalone
node:sqlitescript using a fresh temp dir. On Windows it uses a file symlink, as T3 does. On Linux a hard link gives the same SQLite file naming.Output on Linux (hard link; node 24.18, SQLite 3.53.1):
Output on Windows (file symlink):
The 4152-byte shadow WAL (a 32-byte header plus one frame) holds one committed transaction. The process that wrote it was killed before checkpointing. Afterwards, the main Codex commits and closes cleanly. When the shadow opens the database again, SQLite recovers its own stale WAL, and the next checkpoint writes those pages over the newer ones.
integrity_checkstill reportsok, so the loss is silent. Two other options are also unsafe. Replacing the regular sidecars with links drops the shadow's unapplied commits. Checkpointing the shadow WAL first is safe only if the real database has not changed since that WAL began.What we run locally until this is fixed: a pre-launch sweep, run before T3 starts.
integrity_checkand still contains every row of the real DB.<db>-walwhose links were deleted, if every frame in it is already in the database. Otherwise the next open would replay it over newer pages.None of this addresses the root cause. On Windows the shadow-home Codex should probably not open shared SQLite databases through a link at all. Opening them by their real path, for example through Codex's
sqlite_homeorCODEX_SQLITE_HOMEpointing at the shared home, would give one WAL and one lock table per database. An earlier comment reports sidecars returning even withsqlite_homeset, so that would need checking against the Codex version T3 runs.Mans230 commentedon Oct 24, 2026
Related, but a different failure point: #24486.
This tracker covers the
materializeCodexShadowHomeconflict — a regular shadow entry disabling that instance. #24486 covers what happens when materialization succeeds anyway: the SQLite base file is shared while-wal/-shmstay shadow-local, so the database is corrupted and the defaultcodexprovider (no shadow home) is the one that ends up failing withCodex App Server process exited with code 1/os error 32, on a rebuild loop.Relevant to this issue's acceptance criterion "SQLite families such as the base DB, WAL, and SHM are handled together": the implementation that addressed it here, #19861, was closed on 2026-10-19 without merging, so that criterion currently has nothing in flight.
Worth keeping distinct because an allowlist or self-heal change satisfies this tracker while leaving the WAL split intact — verified locally on
0.1.3-nightly.20261023.3553: with every conflicting shadow entry treated as replaceable,codex-2/codex-3reportreadyand noCodexShadowHomeEntryConflictErroris logged, whilestate_5.sqlitekeeps being rebuilt intodb-backups\sqlite-*every few minutes.CopyJosh commentedon Oct 28, 2026
Note
🤖 GPT-6.1 Terra responding on behalf of CopyJosh
I saw the same shadow-home conflict with
memories.lock.Environment: T3 Code Desktop
0.1.4-nightly.20261028.3824, local server on macOS arm64, Codex CLI0.165.0.Observed: A secondary Codex provider was disabled because
memories.lockexisted as a regular file in both the shared home and the shadow home. Both files were empty. T3 reported that the shadow entry existed and was not a symlink.Source: At commit
eb751fa0730d6a51d56547cb7fcaf4822a7e0e3b, shadow-home setup treatsmemoriesas local, but does not classifymemories.lockas local or replaceable. It attempts to link the shared entry and rejects the regular shadow file.Workaround confirmed: Moved the shadow lock file aside, then disabled and enabled the provider. The provider returned.
aoppenh1-afk commentedon Nov 9, 2026
Additional confirmed filename:
auth.json.lock.Environment: T3 Code Desktop nightly
0.1.8-nightly.20261108.4380on macOS, connected to a remote Linux server running the same version. Codex CLI0.167.0.Failure: Two consecutive runs failed before Codex started:
Cannot create Codex shadow home entry 'auth.json.lock' because '<shadow-home>/auth.json.lock' already exists and is not a symlink.Diagnosis: Empty regular
auth.json.lockfiles existed in both shared and shadow homes.CodexHomeLayout.tsclassifiesauth.lockas private but omitsauth.json.lock; materialization therefore attempts to link it and rejects the regular shadow copy. The original file-creation event was not captured.Reproduction: Create empty regular
auth.json.lockfiles in shared and shadow homes, then materialize the shadow home.Recovery: After confirming neither lock was open or held, backed up the shadow lock and replaced it with the expected symlink. No credentials were changed. Codex login status succeeds; no remaining file conflicts. An authenticated model turn and long-term recurrence remain untested.
The newer nightly
0.1.8-nightly.20261109.4392retains the same classification. Related: #8578.Prepared by GPT-6.1-Sol through the Codex harness in T3 Code.
InvixGG commentedon Nov 11, 2026
Still reproduces on the stable 0.1.8 release with Codex CLI 0.167.1, on macOS arm64 and Windows x64. Two more entries that disabled a shadow-home instance:
memories.lock. An empty (0-byte) regular file existed in both the shared home and the shadow home. In 0.1.8,SHADOW_LOCAL_ENTRY_NAMESislog,memories,tmp,.DS_Store, somemoriesstays local but its siblingmemories.lockis linked, andensureSymlinkrejects the shadow copy:db-backups/. This is a directory (Codex's SQLite backup folder), not a file. In the same shadow home,state_5.sqlite,state_5.sqlite-shmandstate_5.sqlite-walwere also real files, about a week old. So that instance had been running on its own copy of the state DB, with nothing reported in the UI, until the conflict disabled it. That is the [Bug]: Codex shadow home splits each SQLite database from its WAL, corrupting shared state and disabling the default Codex instance #24486 split. I've added the Windows details there.Workaround used: move the conflicting entries out of the shadow home. The next provider settings change triggers a reconcile, which recreates the links. Without that manual step, the instance stays disabled, and the UI shows only the error text.
#32058 (move the real entry into
.t3-shadow-conflicts/and link it) would cover both cases. Whichever fix lands, an empty*.lockbeside a shadow-local entry (memories.locknext tomemories) is probably better kept shadow-local than moved and shared.Aminmiri82 commentedon Nov 12, 2026
Still reproduces on stable 0.1.9 (desktop app, macOS arm64) with Codex CLI 0.167.2, filename
auth.json.lock.Sequence: Codex created an empty regular
auth.json.lockin the shadow home (~/.codex_contact, mtime matches itsauth.json). Later, Codex created another one in the shared home~/.codex. On the next materialization, the shadow instance was disabled. Its provider status cache stopped updating within a minute of the shared lock appearing.Source (v0.1.9 and current main):
PRIVATE_ENTRY_NAMESinCodexHomeLayout.tsis stillauth.json,auth.lock,models_cache.json.auth.json.lockis the lock for the privateauth.json, so it should be private rather than linked. #23428 (auth-like entries private, from #8578) looks like it would cover this; it's still unmerged.Workaround: moved the empty shadow
auth.json.lockaside while nothing held it open (checked withlsof). T3 then links it to the shared lock, so both accounts share one auth lock.Investigated with
t3 triageusing Claude Code (Claude Opus 5.5).loris-olsem commentedon Nov 14, 2026
Note
This comment was investigated, written, and posted by Codex (GPT-6-Astra), acting on behalf of @loris-olsem at their request.
Confirmed recurrence on Windows x64, T3 desktop/local server 0.1.10-nightly.20261114.4669, Codex 0.169.0, on 2026-11-14. This is the same
goals_1.sqlite-shmconflict documented in #20261 (closed into this issue), now on a managed “Connect with ChatGPT” instance.The affected instance had
config: { "setupMode": "managed" }; its shadow home was automatically assigned beneath<T3_DATA>/providers/codex/<instance>/shadow. The default Codex instance was disabled. A primary Codex conversation and Codex workers delegated from a Claude conversation were affected.Observed sequence (UTC):
server.getConfigread returnedstatus: "ready"and 8 models. Existing workspace snapshots includedmodelsPending: true.server.refreshProvidersrequest with{instanceId, fresh: true, refreshModels: true}succeeded. The server configuration subscription also returned ready/8 models. Fresh workspace requests subsequently cleared the pending flags. The user confirmed provider settings and the model picker worked again, without another login or reinstall.Sanitized error:
Installed-code findings:
CodexHomeLayout.ensureSymlinkstill rejects a regular shadow entry unless it is inREPLACEABLE_SHARED_RUNTIME_ENTRIES. That set containsmcp-oauth-locks,thread-writer-locks, and.sqlite-maintenance.lock, but no SQLite sidecars.models: [], retained authenticated status where saved credentials permit it, and the generic reconnect message. This masks the actionable filesystem error. The registry also has model-retention logic, so this is not a claim that every failed check always clears the final published catalog.mergeProviderSnapshotmarks existing workspace catalogs pending when the machine model list changes. The precise reason the open UI did not recover earlier was not isolated; no client update-stream capture was available before recovery.This adds current-version evidence and a misleading recovery-message/UI symptom to the existing issue, rather than proposing deletion/relinking of live SQLite files. #24486 explains why database/WAL/SHM ownership must be handled together. No database corruption was established here, and no new isolated reproduction was run.
Earlier Responses requests also returned 401 “Missing bearer … in header”, and one provider stream closed during compaction. Those are separate observations; this investigation does not establish that the shadow-home conflict caused either, or that the token-catalog issue in #33701 is the same cause.
Prepared by Codex from local logs, the installed bundle, and read-back through T3's API; recovery was confirmed by the user. No credentials, account identifiers, project contents, or raw logs are attached.
fix(server): new Codex home entries no longer disable shadow-home pro…
sittingmongoose commentedon Nov 20, 2026
Two more real-world triggers for this, seen after updating to nightly
0.1.12-nightly.20261120.5009(multi-account layout, oneshadowHomePathper account under~/.codex-t3/<account>/):.sandbox_migration(Windows). Codex had written a regular 3-byte file (v1\n) into two account homes days earlier (Nov 12 and Nov 18). After the update, both providers were disabled at startup:auth.json.lock(macOS). A zero-byte regularauth.json.lockfrom Nov 15 sat in two account homes. Both providers were disabled with the same error namingauth.json.lock.In both cases nothing held the file. Renaming it aside and then toggling the provider off and on in Settings brought the provider back. A T3 restart alone doesn't help until the file is moved, and toggling is needed because the instance error is cached from startup.
So besides newly introduced runtime entries, any pre-existing regular file at a path the shadow home now wants to link (markers and stale locks that Codex leaves behind) disables the provider after an update. Adopting or ignoring stale regular entries, or at least naming the remedy in the error, would avoid a silent loss of the provider.
EdoMon93 commentedon Nov 21, 2026
One more filename:
session_index.jsonl(plussession_index.jsonl.lock), on T3 0.1.11 (Linux server,t3 serve), Codex CLI 0.171.0.Sequence: T3 built the shadow home before Codex had ever created
session_index.jsonlin the shared home. Codex later created it in the shared home, and separately created a real file in the shadow home the first time that account named a thread. The next T3 restart disabled the shadow-home provider.Why this case matters: Unlike the lock,
-shm/-waland cache files reported above, this file has content: Codex thread names, one JSON line per thread ID. The shadow copy held entries that weren't in the shared file, so deleting it loses those thread names. Recovery here meant appending the shadow-only lines to the shared file (deduplicated byid), moving the shadowsession_index.jsonland.lockaside, and restarting T3. Any automatic reconciliation should merge files like this one rather than discard the shadow copy.